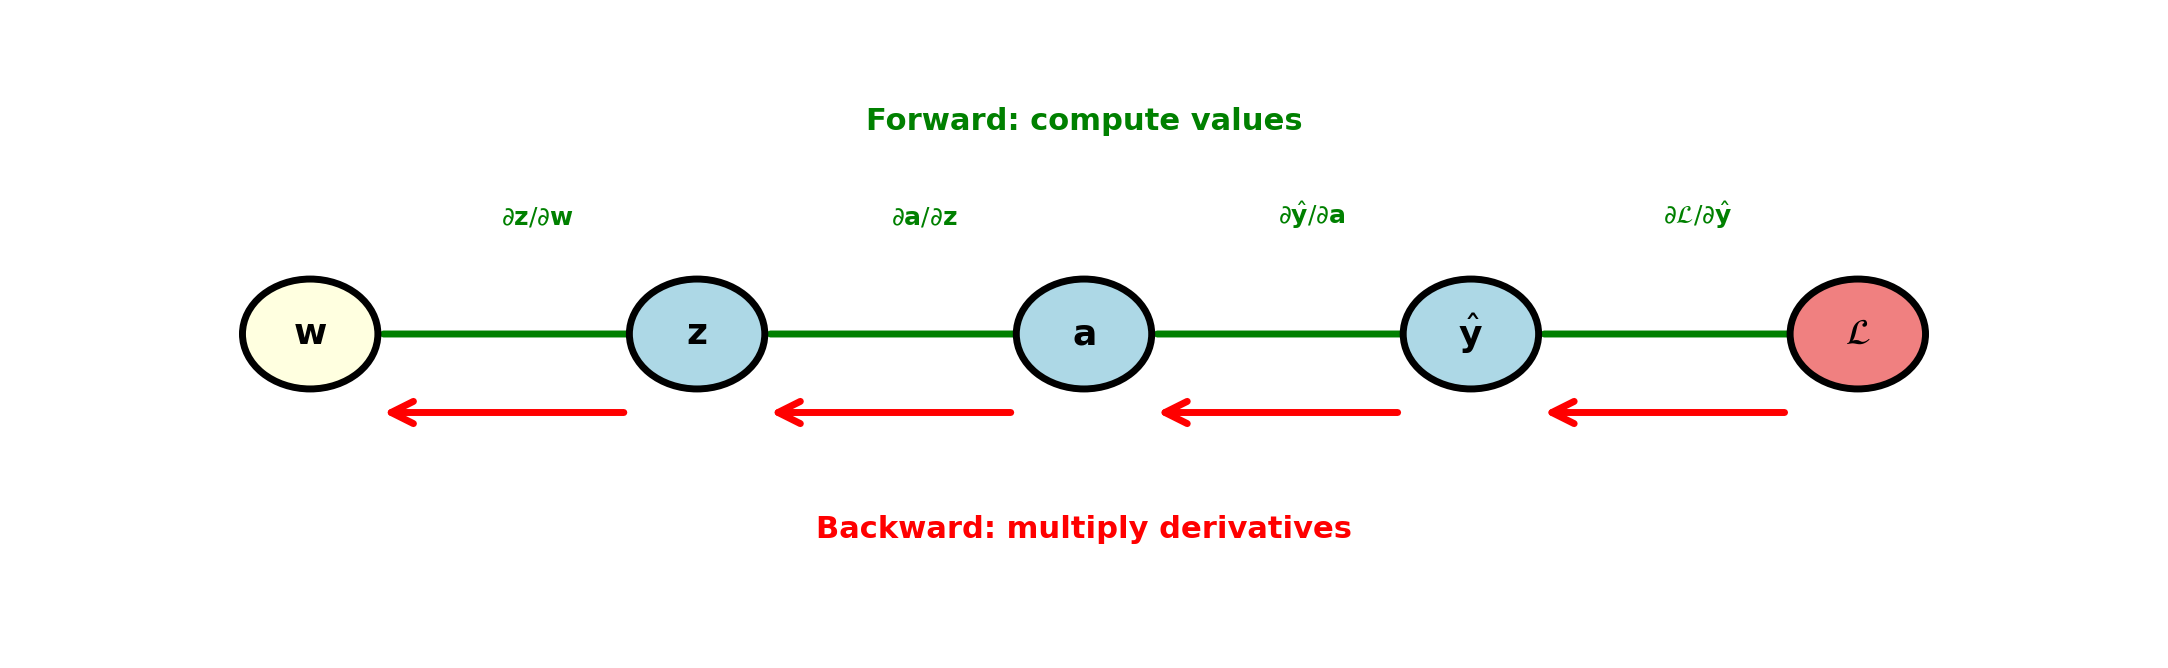
Backpropagation
EE 541 - Unit 6
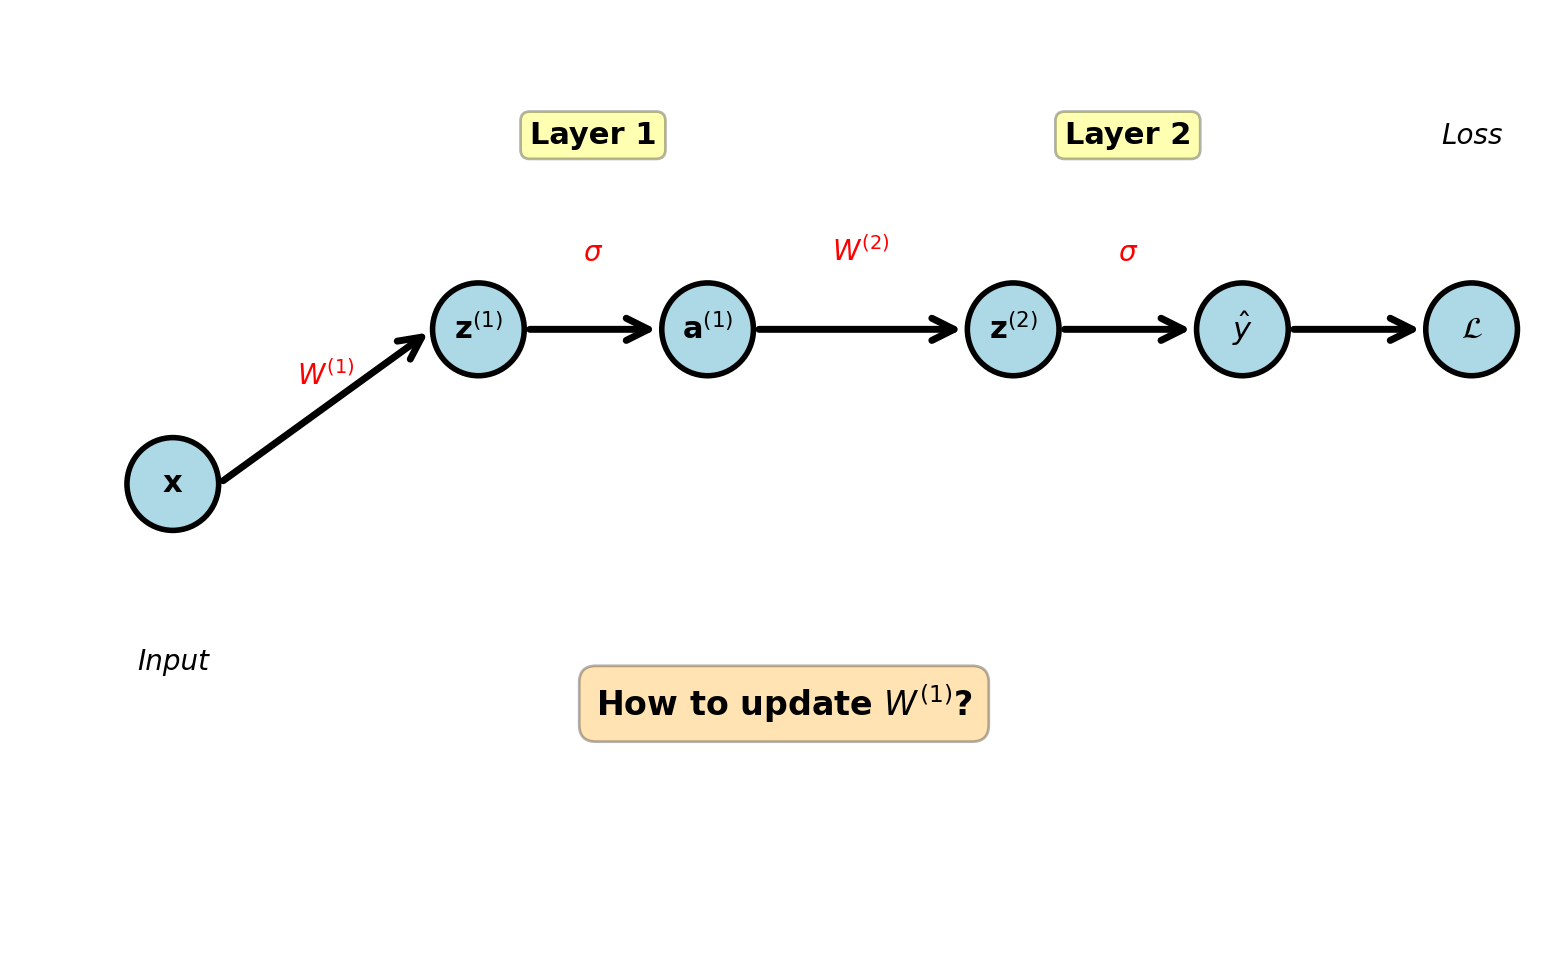
Superscript \((l)\) Indexes the Layer
Layer index in parentheses, not a power
- \(\mathbf{W}^{(1)} \in \mathbb{R}^{m \times d}\), \(\;\mathbf{b}^{(1)} \in \mathbb{R}^{m}\)
- \(\mathbf{W}^{(2)} \in \mathbb{R}^{1 \times m}\), \(\;\mathbf{b}^{(2)} \in \mathbb{R}\)
- \(\mathbf{a}^{(l)}\): the output of layer \(l\), with \(\mathbf{a}^{(0)} = \mathbf{x}\)
Both weight sets are matrices
- One row per unit, one column per input to the layer
- The output layer has one unit, so one row
- One index per layer, so the notation extends to any depth
Renaming only: the network is unchanged (figure)
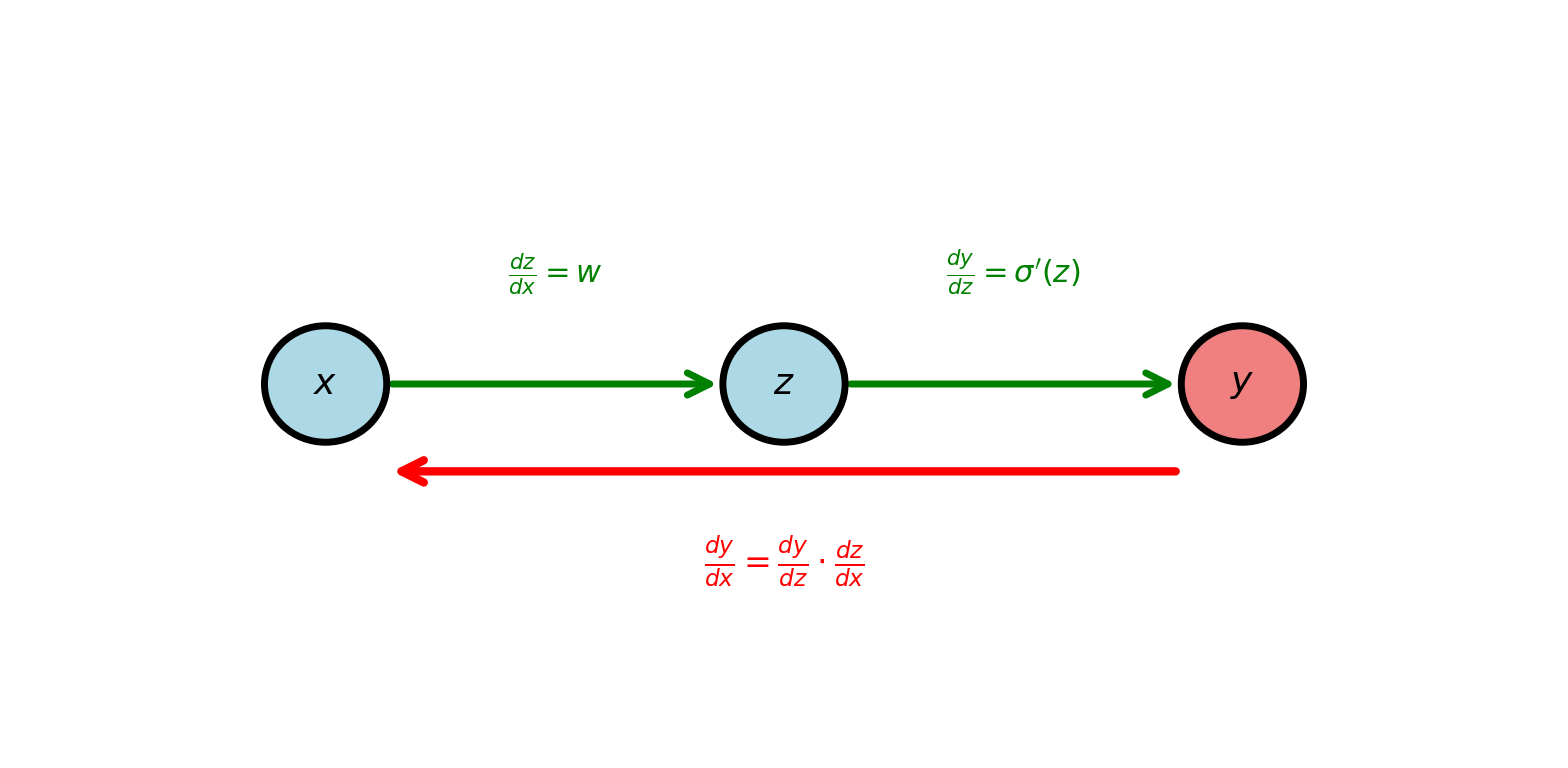
\(\partial \ell / \partial \mathbf{W}^{(1)}\) Expands Through the Output Unit
Same form as one neuron \[\frac{\partial \ell}{\partial \mathbf{W}^{(1)}} = \frac{\partial \ell}{\partial \mathbf{s}^{(1)}} \cdot \frac{\partial \mathbf{s}^{(1)}}{\partial \mathbf{W}^{(1)}}\]
- Second factor: the input \(\mathbf{x}\), as before
- First factor: the loss derivative at the hidden pre-activation, where one neuron had \(\pi - y\)
First factor expands through the output unit \[\frac{\partial \ell}{\partial \mathbf{s}^{(1)}} = \underbrace{\frac{\partial \ell}{\partial \hat{y}}}_{\text{loss slope}} \cdot \underbrace{\frac{d\hat{y}}{ds^{(2)}}}_{\sigma'(s^{(2)})} \cdot \underbrace{\frac{\partial s^{(2)}}{\partial \mathbf{a}^{(1)}}}_{\mathbf{W}^{(2)}} \cdot \underbrace{\frac{\partial \mathbf{a}^{(1)}}{\partial \mathbf{s}^{(1)}}}_{\sigma'(\mathbf{s}^{(1)})}\]
- Loss to output: \(\partial \ell / \partial \hat{y}\), from comparing \(\hat{y}\) with \(y\)
- Output unit’s slope: \(\sigma'(s^{(2)})\)
- Output unit’s weights: \(\mathbf{W}^{(2)}\)
- Hidden units’ slopes: \(\sigma'(\mathbf{s}^{(1)})\)
First two factors are also in \(\partial \ell / \partial \mathbf{W}^{(2)}\): \(\;\partial \ell / \partial \hat{y} \cdot \sigma'(s^{(2)}) \cdot \mathbf{a}^{(1)}\)
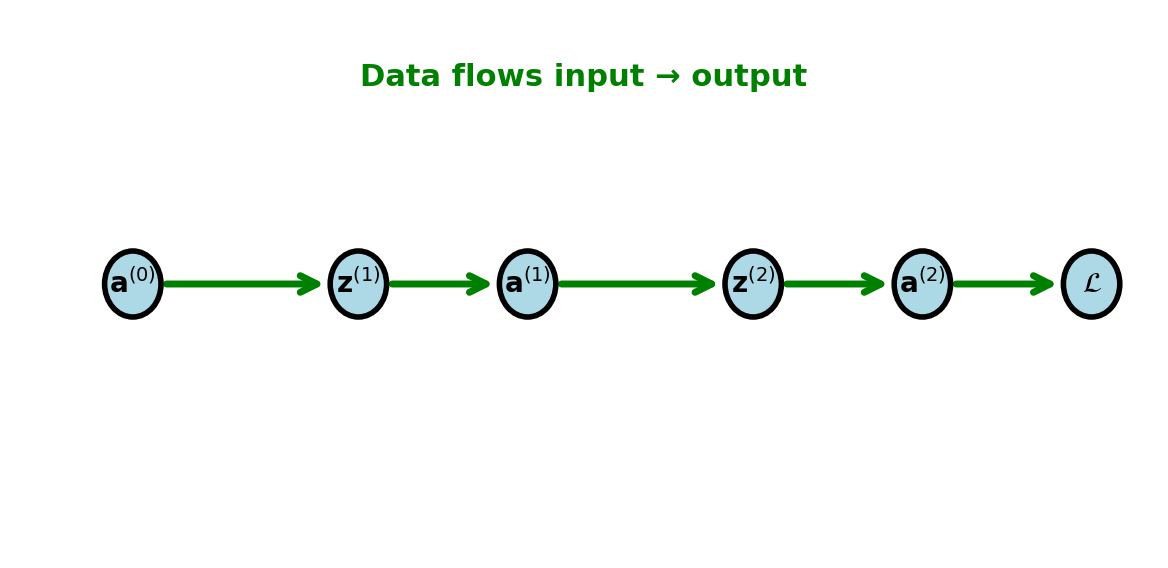
Forward Pass: Every Layer Computes \(\mathbf{s} = \mathbf{W}\mathbf{a} + \mathbf{b}\), Then \(\mathbf{a} = \sigma(\mathbf{s})\)
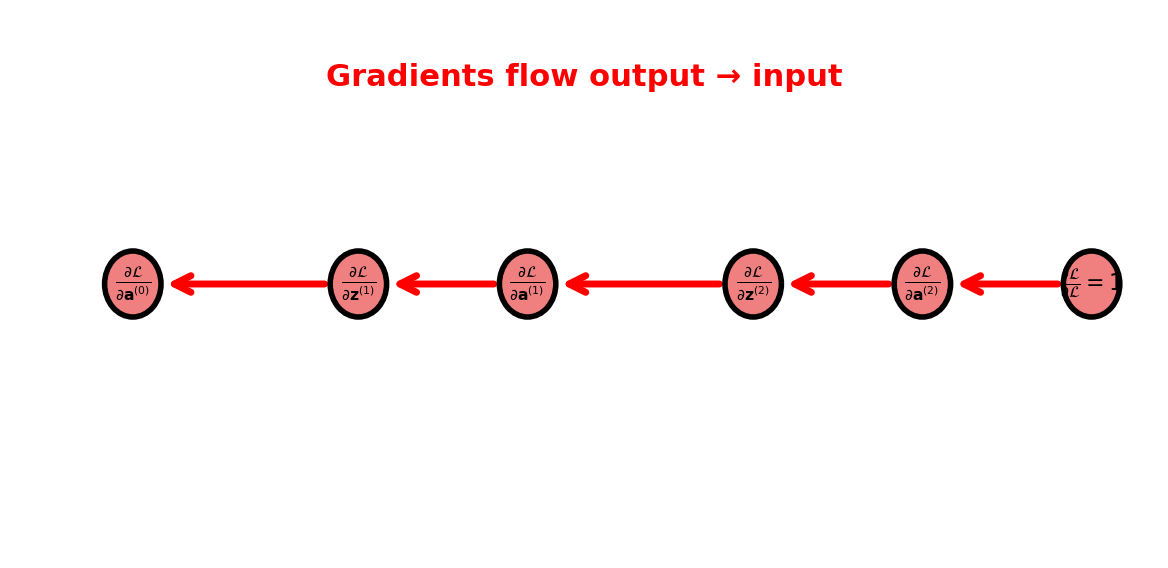
Layer \(l = 1, \ldots, L\) \[\mathbf{s}^{(l)} = \mathbf{W}^{(l)}\mathbf{a}^{(l-1)} + \mathbf{b}^{(l)}, \qquad \mathbf{a}^{(l)} = \sigma^{(l)}(\mathbf{s}^{(l)})\]
- \(\mathbf{W}^{(l)} \in \mathbb{R}^{n_l \times n_{l-1}}\), \(\;\mathbf{b}^{(l)} \in \mathbb{R}^{n_l}\), with \(n_0 = d\)
- \(\mathbf{a}^{(0)} = \mathbf{x}\), \(\;\mathbf{a}^{(L)} = \hat{\mathbf{y}}\), loss \(\ell(\hat{\mathbf{y}}, y)\)
Pre-activation and activation
- \(\mathbf{s}^{(l)}\): linear in \(\mathbf{W}^{(l)}\)
- \(\mathbf{a}^{(l)}\): the next layer’s input
Activation \(\sigma^{(l)}\) can differ by layer
- Hidden layers: sigmoid, or ReLU, \(\sigma(s) = \max(s, 0)\)
- Output layer: sigmoid or softmax
Two-layer network: \(L = 2\), \(n_2 = 1\)
Backward Pass: Two Factors per Layer, Its Slope and Its Weights
Three derivatives per layer
- Activation: \(\partial \mathbf{a}^{(l)} / \partial \mathbf{s}^{(l)} = \sigma'(\mathbf{s}^{(l)})\)
- Previous layer’s output: \(\partial \mathbf{s}^{(l)} / \partial \mathbf{a}^{(l-1)} = \mathbf{W}^{(l)}\)
- Own weights: \(\partial \mathbf{s}^{(l)} / \partial \mathbf{W}^{(l)} = \mathbf{a}^{(l-1)}\)
From the loss to the input, given \(\partial \ell / \partial \mathbf{a}^{(l)}\)
- Times \(\sigma'(\mathbf{s}^{(l)})\) and \(\mathbf{W}^{(l)}\): \(\partial \ell / \partial \mathbf{a}^{(l-1)}\), the previous layer’s output gradient
- Times \(\sigma'(\mathbf{s}^{(l)})\) and \(\mathbf{a}^{(l-1)}\): \(\partial \ell / \partial \mathbf{W}^{(l)}\), this layer’s weight gradient
Target appears once, in \(\partial \ell / \partial \hat{\mathbf{y}}\), and every other factor is a slope, a weight matrix, or an input
Derivative of a Composition Is a Product
Composition of \(L\) functions, \(u_k = f_k(u_{k-1})\), \(u_0 = x\) \[y = f_L(\cdots f_2(f_1(x))), \qquad \frac{dy}{dx} = f_L'(u_{L-1}) \cdots f_2'(u_1)\, f_1'(u_0)\]
- One factor per function
- \(f_k'\) evaluated at its own input \(u_{k-1}\)
Example: \(u_1 = 3x + 1\), \(\;u_2 = \sigma(u_1)\), \(\;y = u_2^2\), at \(x = 0.5\)
- \(u_1 = 2.5\), \(\;u_2 = 0.924\), \(\;y = 0.854\)
- \(f_1' = 3\), \(\;f_2' = \sigma'(2.5) = 0.0701\), \(\;f_3' = 2u_2 = 1.848\)
- \(dy/dx = 1.848 \times 0.0701 \times 3 = 0.389\)
Logistic neuron, \(L = 3\): \(\;f_1 = \mathbf{w}^T\mathbf{x} + b\), \(\;f_2 = \sigma\), \(\;f_3 = \ell\)
Forward values appear in the derivative: \(\sigma'\) at \(u_1 = 2.5\), not at \(x\)
Contributions From Different Paths Add
Two paths from \(x\) to \(z\): \(\;z = f(u, v)\), \(\;u = g(x)\), \(\;v = h(x)\) \[\frac{dz}{dx} = \frac{\partial f}{\partial u}\, g'(x) + \frac{\partial f}{\partial v}\, h'(x)\]
- One product per path
- Products add
Example: \(u = 2x\), \(\;v = x^2\), \(\;z = uv\), at \(x = 1.5\)
- \(u = 3\), \(\;v = 2.25\), \(\;z = 6.75\)
- Path through \(u\): \(v \cdot 2 = 4.5\)
- Path through \(v\): \(u \cdot 2x = 9\)
- Sum: \(13.5\)
- Check: \(z = 2x^3\), \(\;6x^2 = 13.5\)
Hidden unit with \(K\) units after it: \(K\) paths to the loss
- \(K\) products, summed
Forward Pass Produces Every Value the Backward Pass Needs
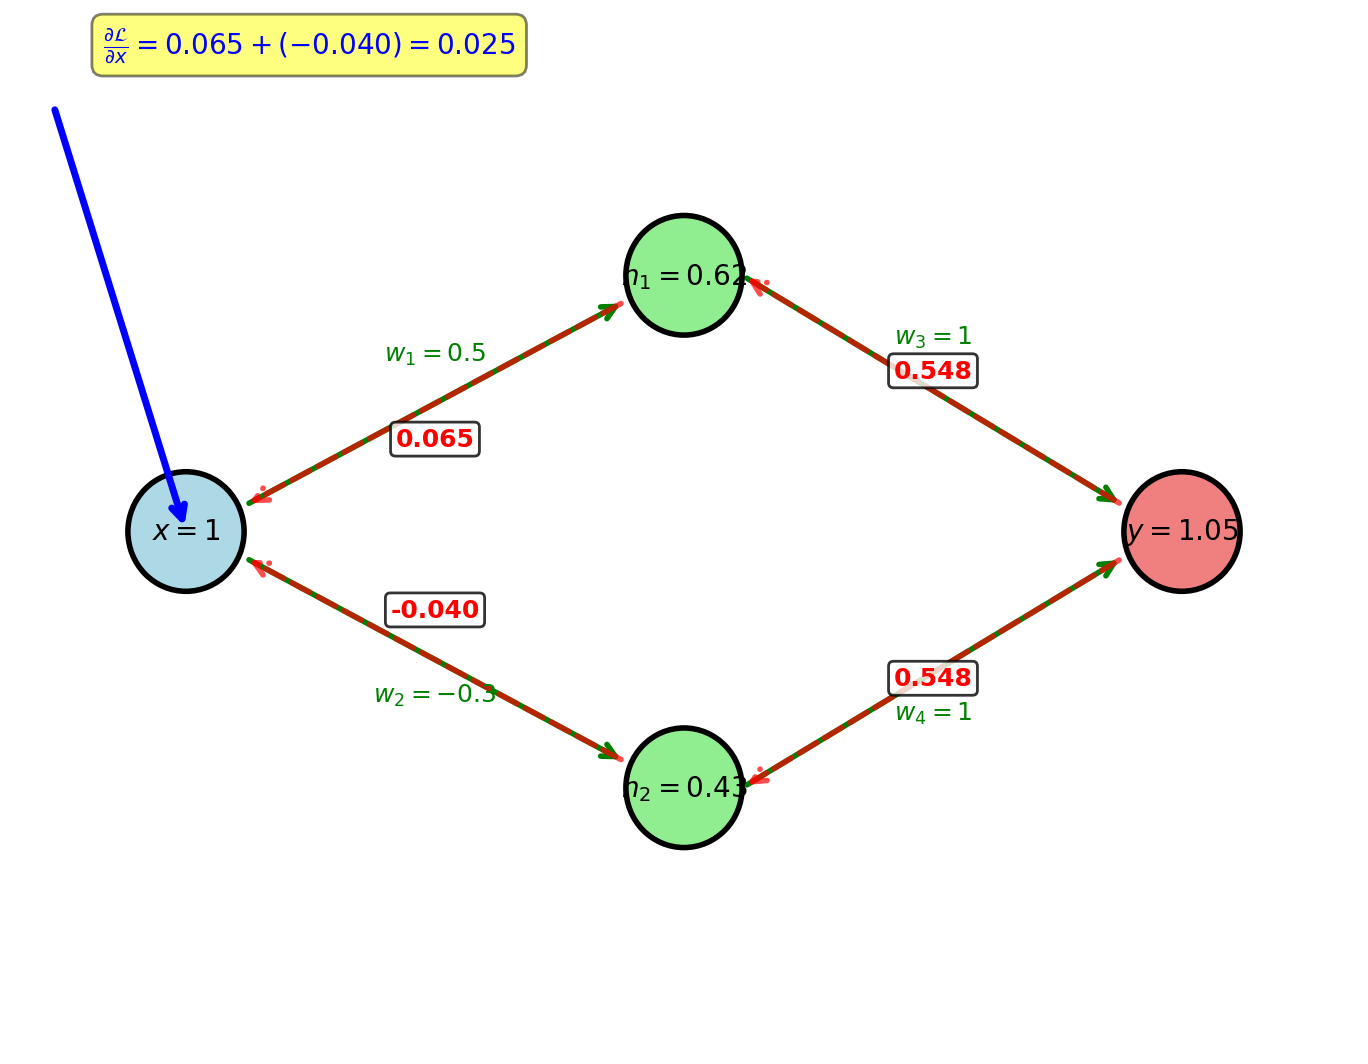
One unit per layer: every weight, pre-activation, and activation is a single number
- Every chain-rule factor is a plain multiplication
- The vector case repeats the same steps with matrices
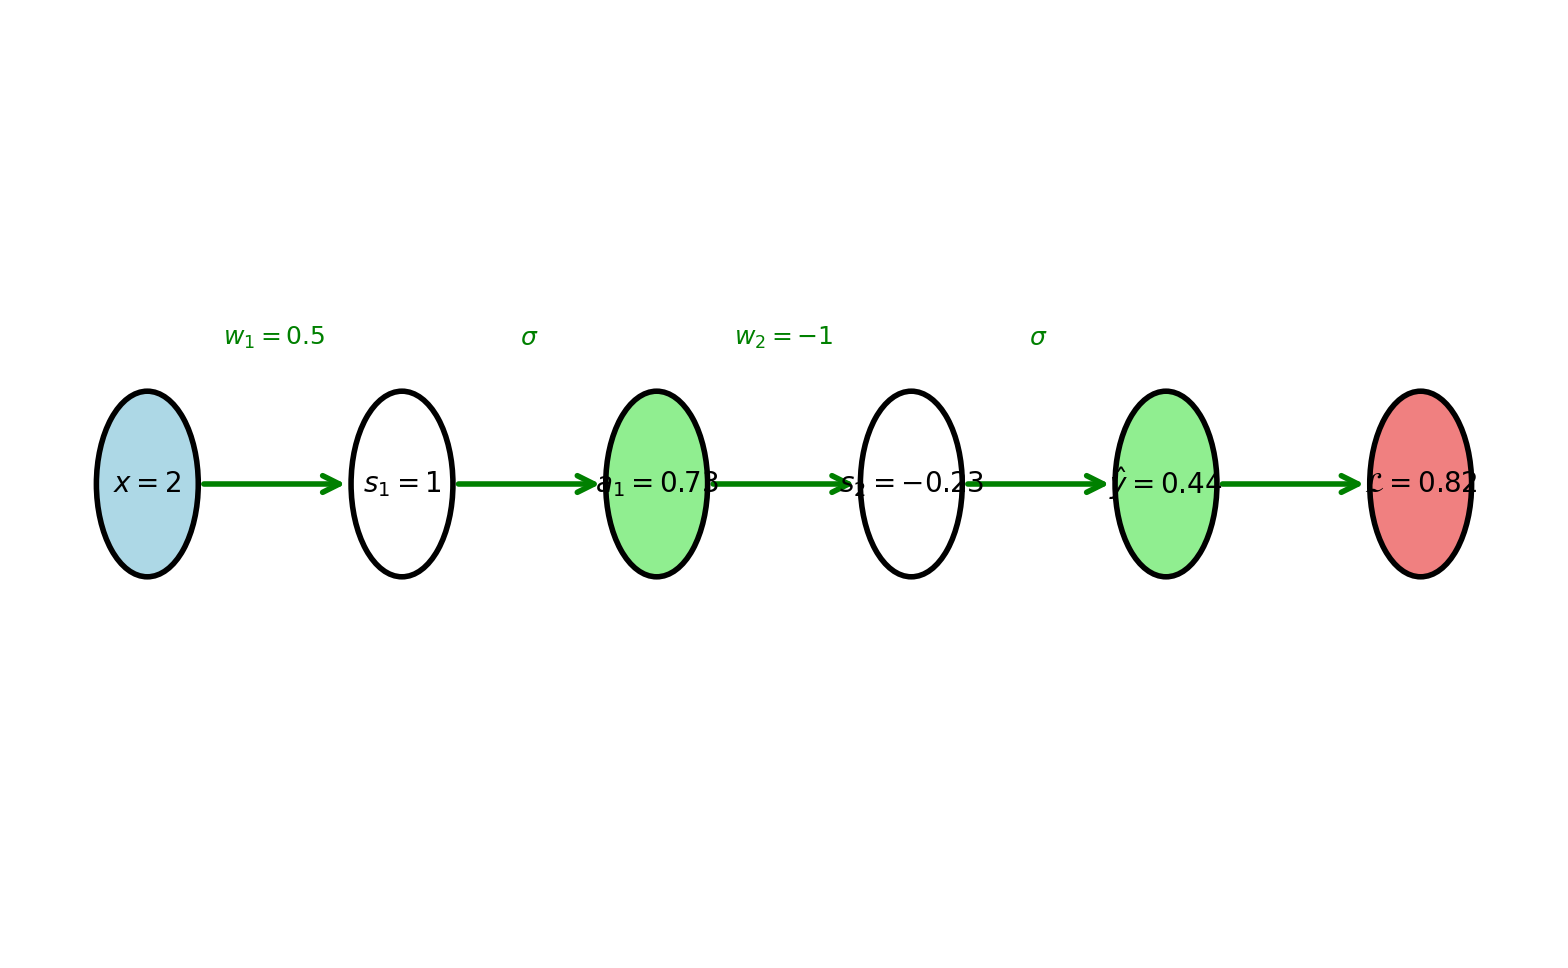
Parameters: \(w^{(1)} = 0.5\), \(\;b^{(1)} = 0\), \(\;w^{(2)} = -1\), \(\;b^{(2)} = 0.5\)
Input and target: \(x = 2\), \(\;y = 1\)
Kept for the backward pass: \(a^{(1)}\) (the output weight’s input), \(s^{(1)}\), \(s^{(2)}\)
Forward pass, one line per operation \[s^{(1)} = w^{(1)} x + b^{(1)} = 0.5 \cdot 2 + 0 = 1\] \[a^{(1)} = \sigma(s^{(1)}) = \sigma(1) = 0.731\] \[s^{(2)} = w^{(2)} a^{(1)} + b^{(2)} = -0.731 + 0.5 = -0.231\] \[\hat{y} = \sigma(s^{(2)}) = 0.442, \qquad \ell = -\log \hat{y} = 0.815\]
Output Weight: Logistic Regression’s Gradient With Input \(a^{(1)}\)
Chain rule on \(w^{(2)}\): \(\ell\) depends on \(w^{(2)}\) through \(s^{(2)}\), then \(\hat{y}\) \[\frac{\partial \ell}{\partial w^{(2)}} = \frac{\partial \ell}{\partial \hat{y}} \cdot \frac{d\hat{y}}{ds^{(2)}} \cdot \frac{\partial s^{(2)}}{\partial w^{(2)}}\]
Each factor from the forward values
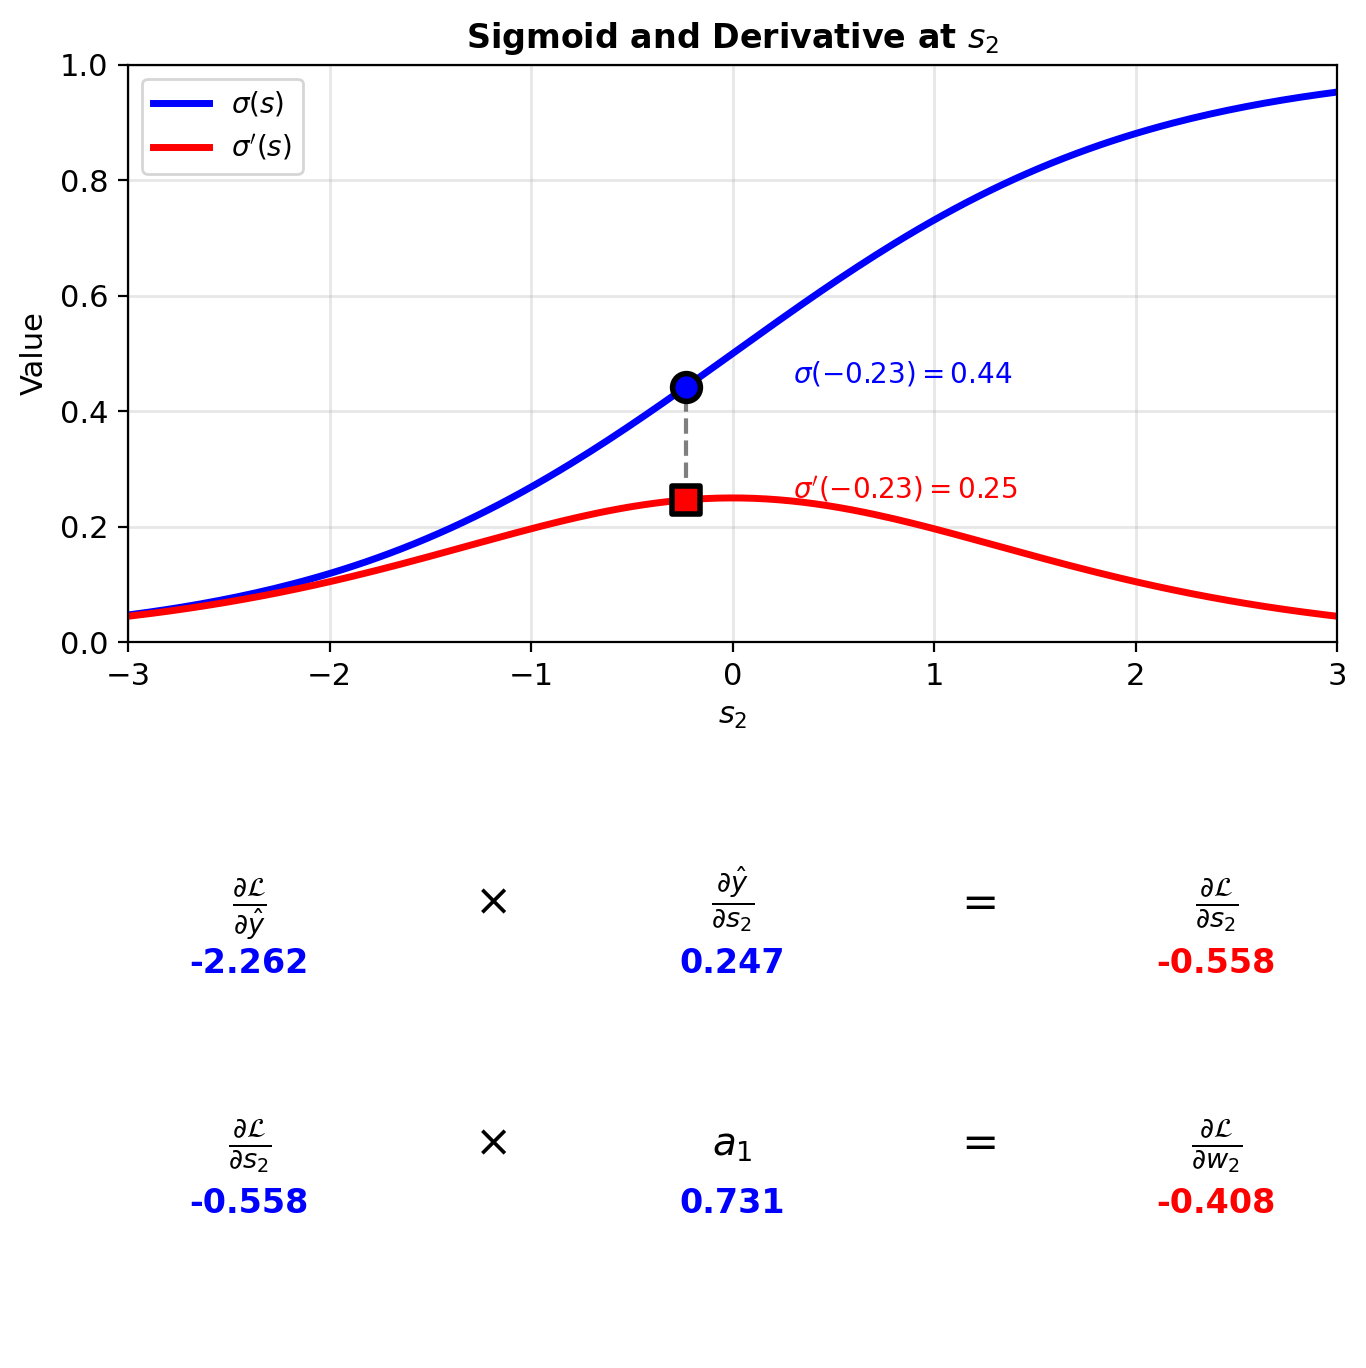
- Loss slope: \(\partial \ell / \partial \hat{y} = -1/\hat{y} = -2.260\)
- Activation slope: \(\sigma'(s^{(2)}) = \hat{y}(1 - \hat{y}) = 0.247\)
- Input to the weight: \(a^{(1)} = 0.731\)
Substituted \[\frac{\partial \ell}{\partial w^{(2)}} = (-2.260)(0.247)(0.731) = -0.408\]
Bias, the same two slopes with input \(1\) \[\frac{\partial \ell}{\partial b^{(2)}} = (-2.260)(0.247) = -0.558\]
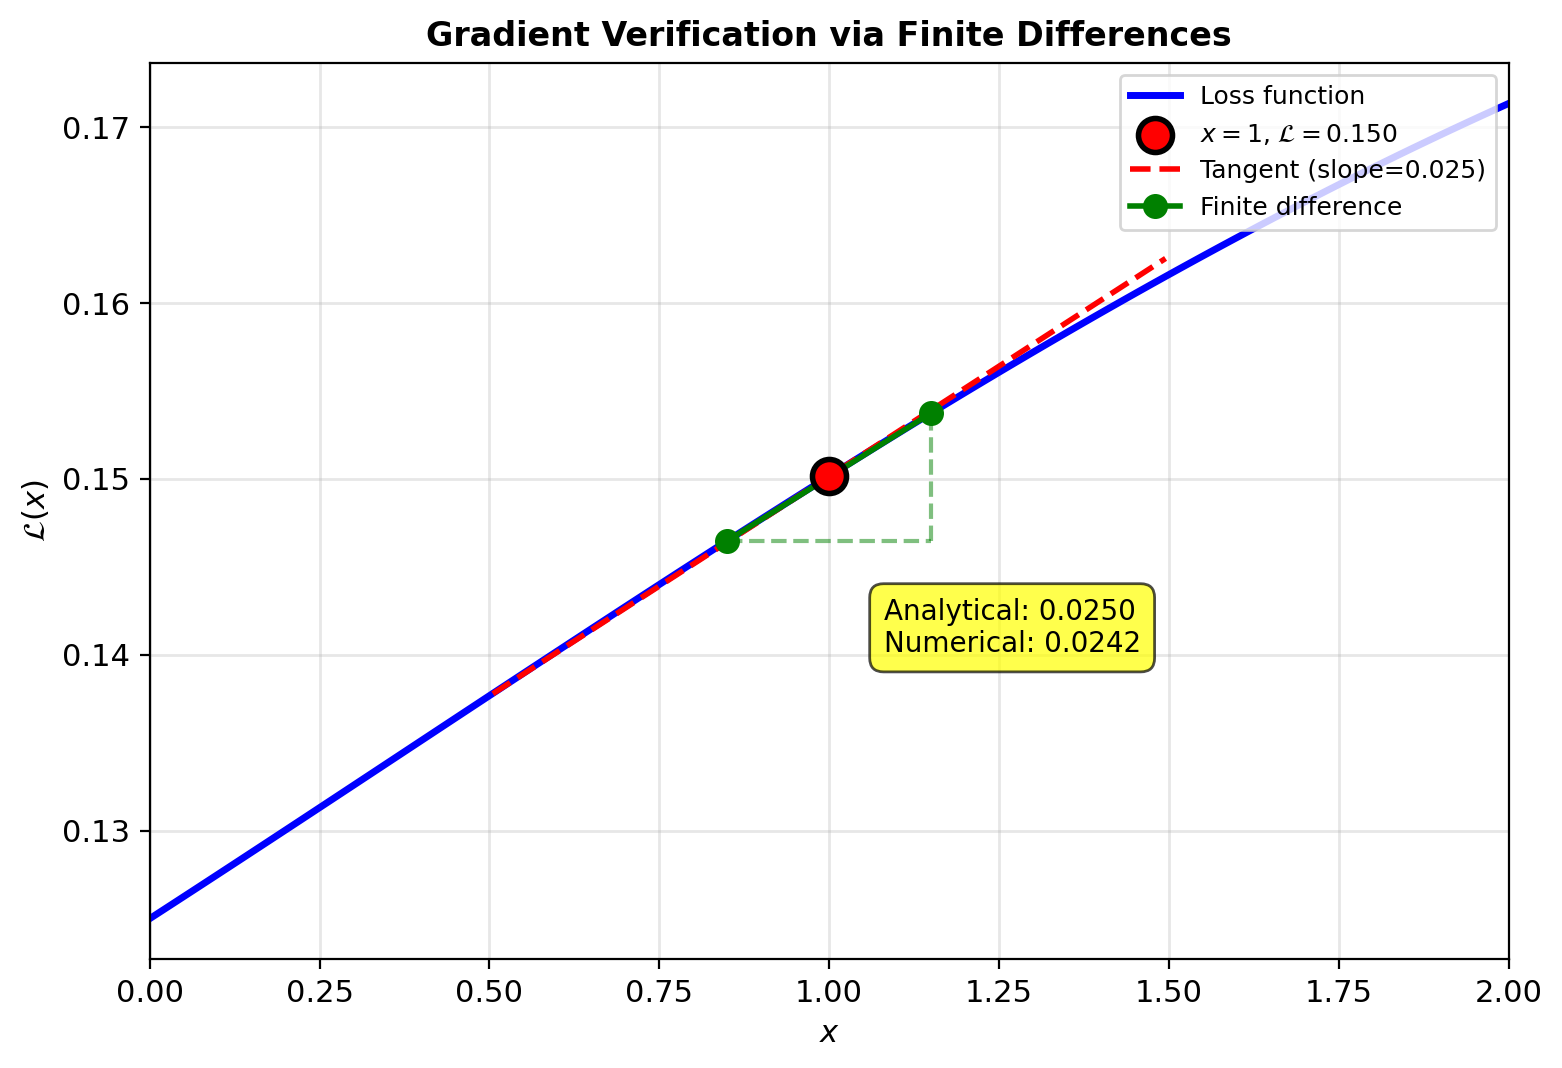
Two slopes multiply to \(\hat{y} - y = -0.558\): the prediction error, as for one logistic neuron
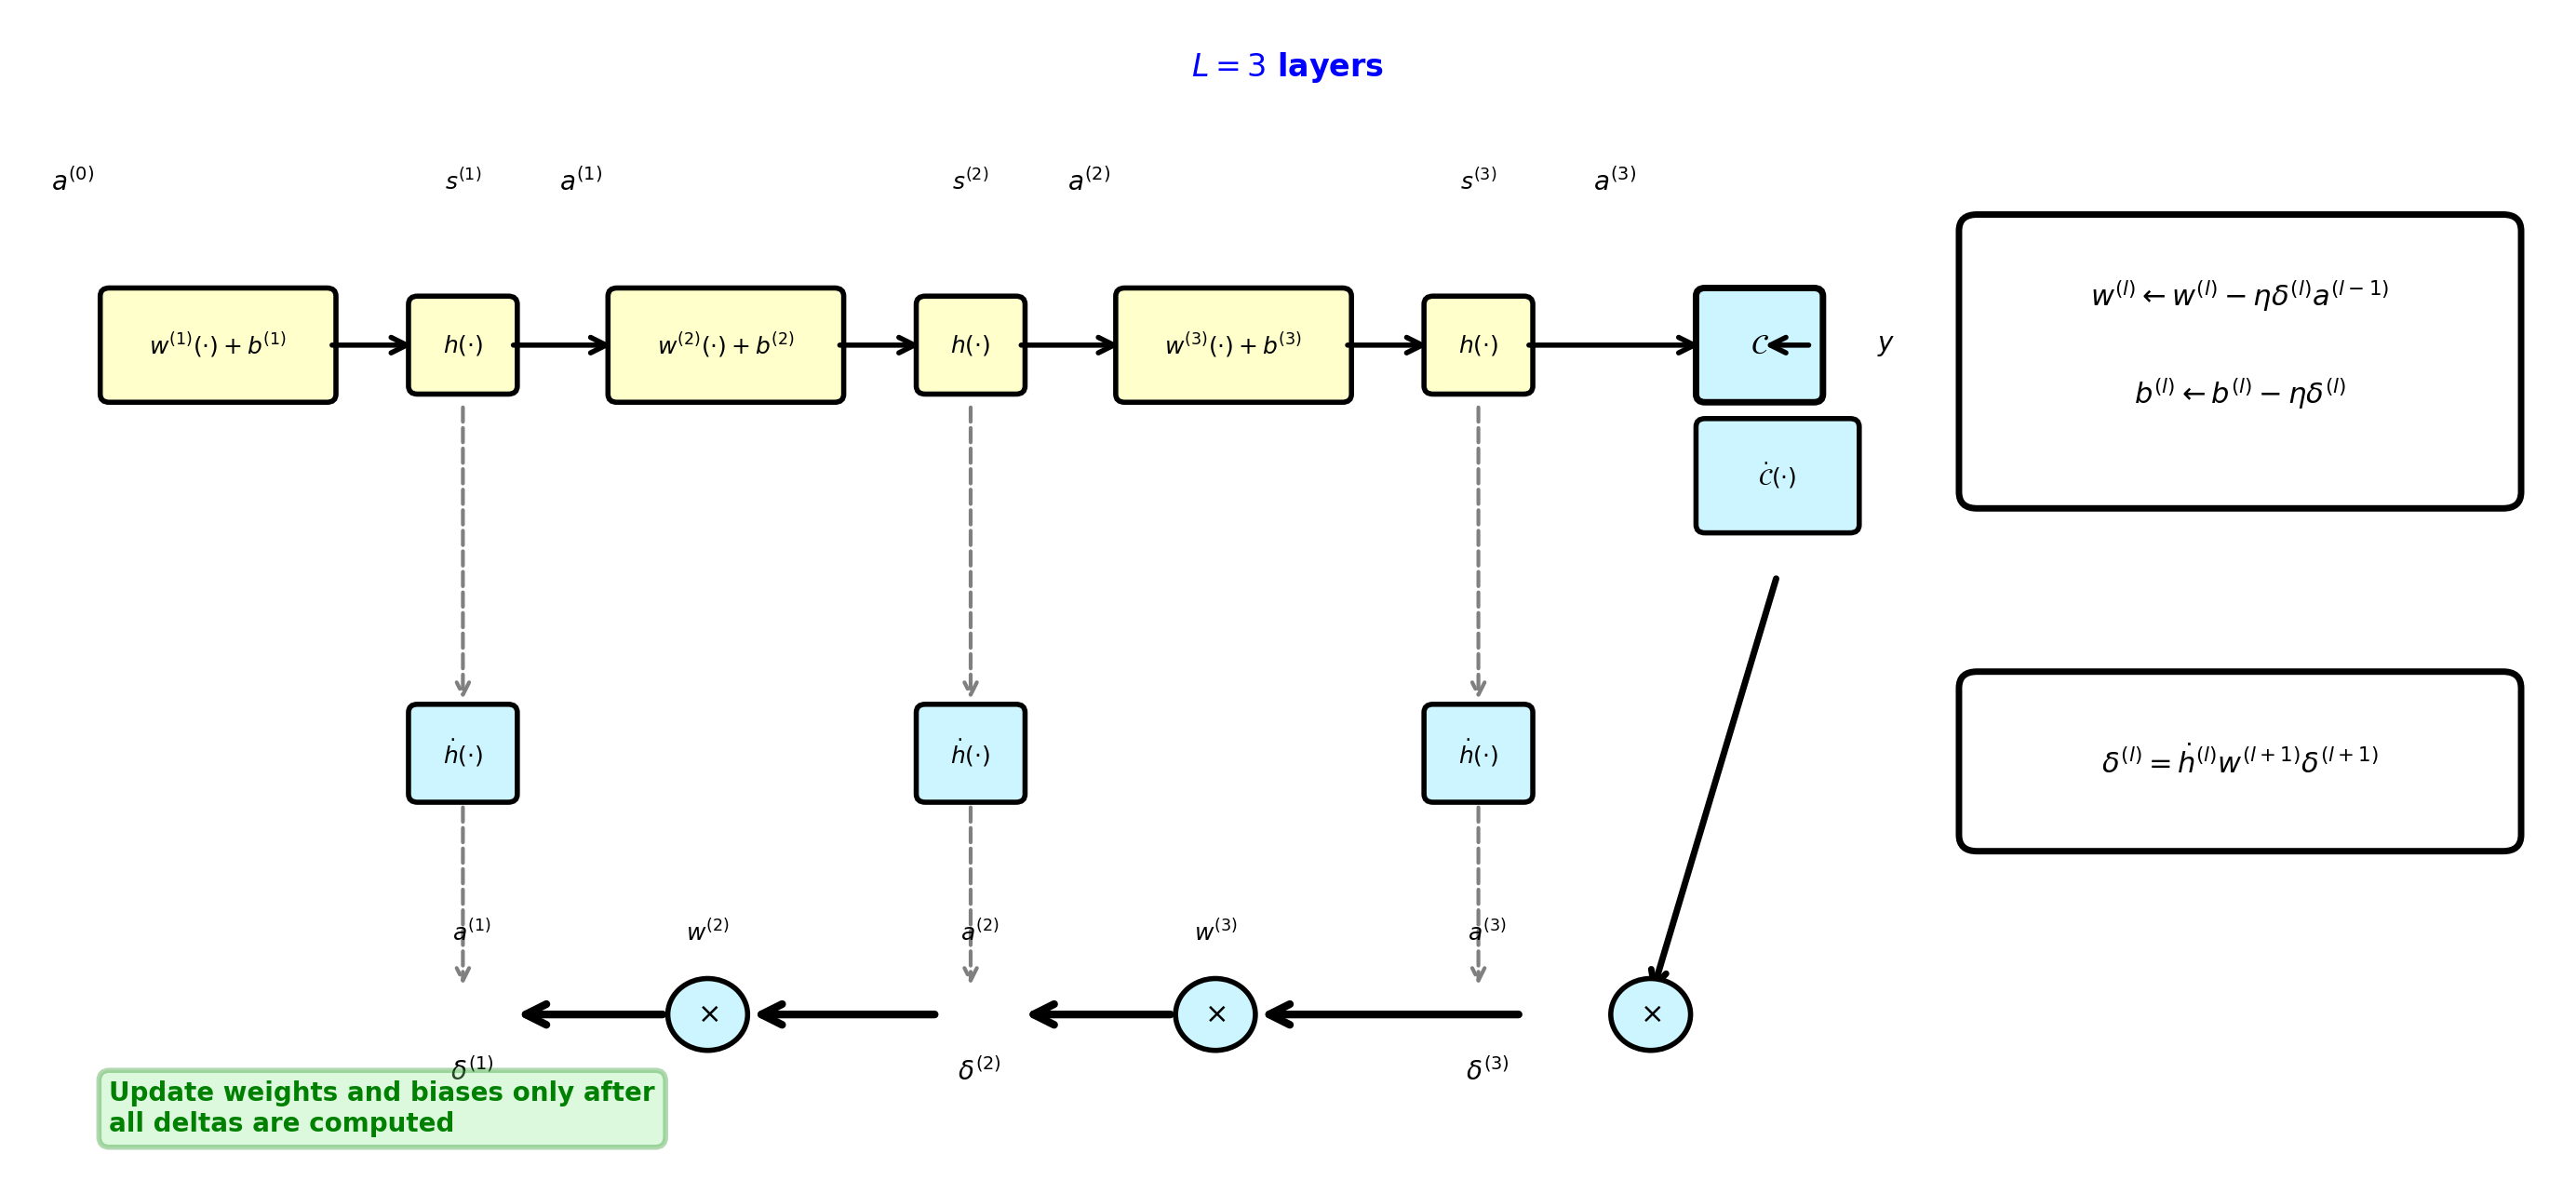
\(\delta\): Gradient at the Pre-Activation
Definition \[\delta^{(l)} = \frac{\partial \ell}{\partial s^{(l)}}\]
Already in both gradients, as the bracketed product before the input
- \(\partial \ell / \partial w^{(2)} = \big[\partial \ell / \partial \hat{y} \cdot \sigma'(s^{(2)})\big] \cdot a^{(1)} = \delta^{(2)} a^{(1)}\), with \(\delta^{(2)} = -0.558\)
- \(\partial \ell / \partial w^{(1)} = \big[\delta^{(2)} \cdot w^{(2)} \cdot \sigma'(s^{(1)})\big] \cdot x = \delta^{(1)} x\), with \(\delta^{(1)} = 0.110\)
At the output: \(\delta^{(2)} = \hat{y} - y\), the prediction error
At the hidden layer: \(\delta^{(1)}\) is a derivative with no target behind it
One number per layer: each parameter’s gradient is \(\delta^{(l)}\) times that parameter’s input
- Weight: \(\partial \ell / \partial w^{(l)} = \delta^{(l)}\, a^{(l-1)}\)
- Bias: \(\partial \ell / \partial b^{(l)} = \delta^{(l)}\)
Backward Pass: Recursion From Output to Input
Initialize at the output: \(\delta^{(L)} = \partial \ell / \partial \hat{y} \cdot \sigma'(s^{(L)})\)
Propagate one layer at a time: \(\delta^{(l)} = \delta^{(l+1)}\, w^{(l+1)}\, \sigma'(s^{(l)})\)
Read off at every layer: \(\partial \ell / \partial w^{(l)} = \delta^{(l)} a^{(l-1)}\), \(\;\partial \ell / \partial b^{(l)} = \delta^{(l)}\)
Branching: Each Branch Adds a Term to \(\partial \ell / \partial a^{(1)}\)
Hidden unit’s output branches to two output units, loss \(\ell = \ell_1 + \ell_2\), subscripts \(1\) and \(2\) indexing the output units
\(w^{(3)} = -1\), \(\;b^{(3)} = 0.5\), \(\;w^{(4)} = 1\), \(\;b^{(4)} = 0\)
\(\hat{y}_1 = \sigma(w^{(3)} a^{(1)} + b^{(3)}) = 0.442\), target \(y_1 = 1\)
\(\hat{y}_2 = \sigma(w^{(4)} a^{(1)} + b^{(4)}) = 0.675\), target \(y_2 = 0\)
At each output, as for one neuron
- \(\delta_1 = \hat{y}_1 - y_1 = -0.558\)
- \(\delta_2 = \hat{y}_2 - y_2 = 0.675\)
At the branch point, each branch contributes a term \[\frac{\partial \ell}{\partial a^{(1)}} = \delta_1 w^{(3)} + \delta_2 w^{(4)} = (-0.558)(-1) + (0.675)(1) = 1.233\]
From \(a^{(1)}\) to \(w^{(1)}\), the single chain as before
- \(\delta^{(1)} = 1.233 \times \sigma'(s^{(1)}) = 0.242\)
- \(\partial \ell / \partial w^{(1)} = 0.242 \times 2 = 0.485\)
\(K\) branches: \(K\) terms, which the vector form writes as \(\mathbf{W}^T \boldsymbol{\delta}\)
Forward Pass: One Matrix Product per Layer
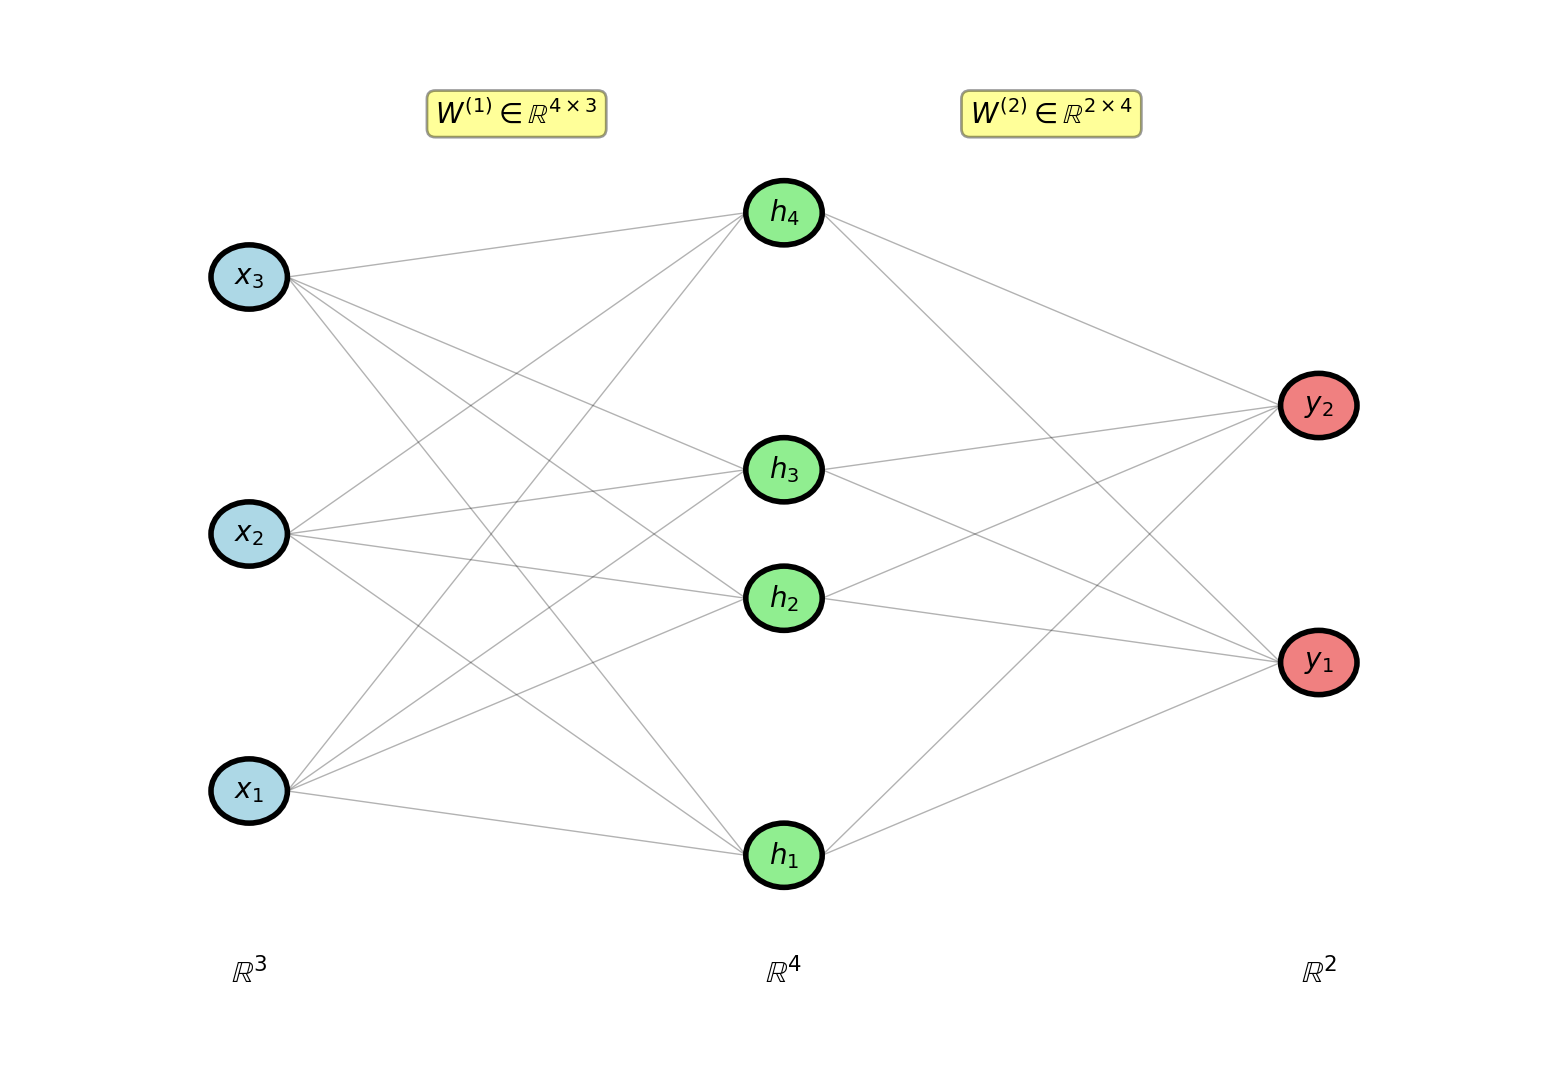
3-4-2 network: 3 inputs, 4 sigmoid hidden units, 2 softmax outputs, cross-entropy
Layer as a matrix: row \(i\) of \(\mathbf{W}^{(l)}\) is unit \(i\)’s weight vector \[\mathbf{s}^{(l)} = \mathbf{W}^{(l)} \mathbf{a}^{(l-1)} + \mathbf{b}^{(l)}, \qquad \mathbf{W}^{(l)} \in \mathbb{R}^{n_l \times n_{l-1}}\]
First layer \[\mathbf{W}^{(1)} = \begin{bmatrix} 0.1 & 0.2 & -0.1 \\ 0.3 & -0.2 & 0.1 \\ -0.1 & 0.1 & 0.2 \\ 0.2 & 0.3 & -0.3 \end{bmatrix}\] \[\mathbf{b}^{(1)} = \begin{bmatrix} 0.1 \\ -0.1 \\ 0 \\ 0.2 \end{bmatrix}, \qquad \mathbf{x} = \begin{bmatrix} 1 \\ 0.5 \\ -0.5 \end{bmatrix}\] \[\mathbf{W}^{(2)} = \begin{bmatrix} 0.5 & -0.3 & 0.2 & 0.1 \\ -0.2 & 0.4 & -0.1 & 0.3 \end{bmatrix}, \qquad \mathbf{b}^{(2)} = \begin{bmatrix} 0 \\ 0.1 \end{bmatrix}\]
Unit 1, row 1 against \(\mathbf{x}\): \(\;s^{(1)}_1 = 0.1 (1) + 0.2 (0.5) + (-0.1)(-0.5) + 0.1 = 0.35\)
Forward pass, one product per layer
- \(\mathbf{s}^{(1)} = \mathbf{W}^{(1)} \mathbf{x} + \mathbf{b}^{(1)} = [0.35,\ 0.05,\ -0.15,\ 0.70]^T\)
- \(\mathbf{a}^{(1)} = \sigma(\mathbf{s}^{(1)}) = [0.587,\ 0.512,\ 0.463,\ 0.668]^T\)
- \(\mathbf{s}^{(2)} = \mathbf{W}^{(2)} \mathbf{a}^{(1)} + \mathbf{b}^{(2)} = [0.299,\ 0.342]^T\)
- \(\hat{\mathbf{y}} = \mathrm{softmax}(\mathbf{s}^{(2)}) = [0.489,\ 0.511]^T\), \(\;\ell = -\log 0.511 = 0.672\) for target \(\mathbf{y} = [0,\ 1]^T\)
Each Weight Affects One Pre-Activation
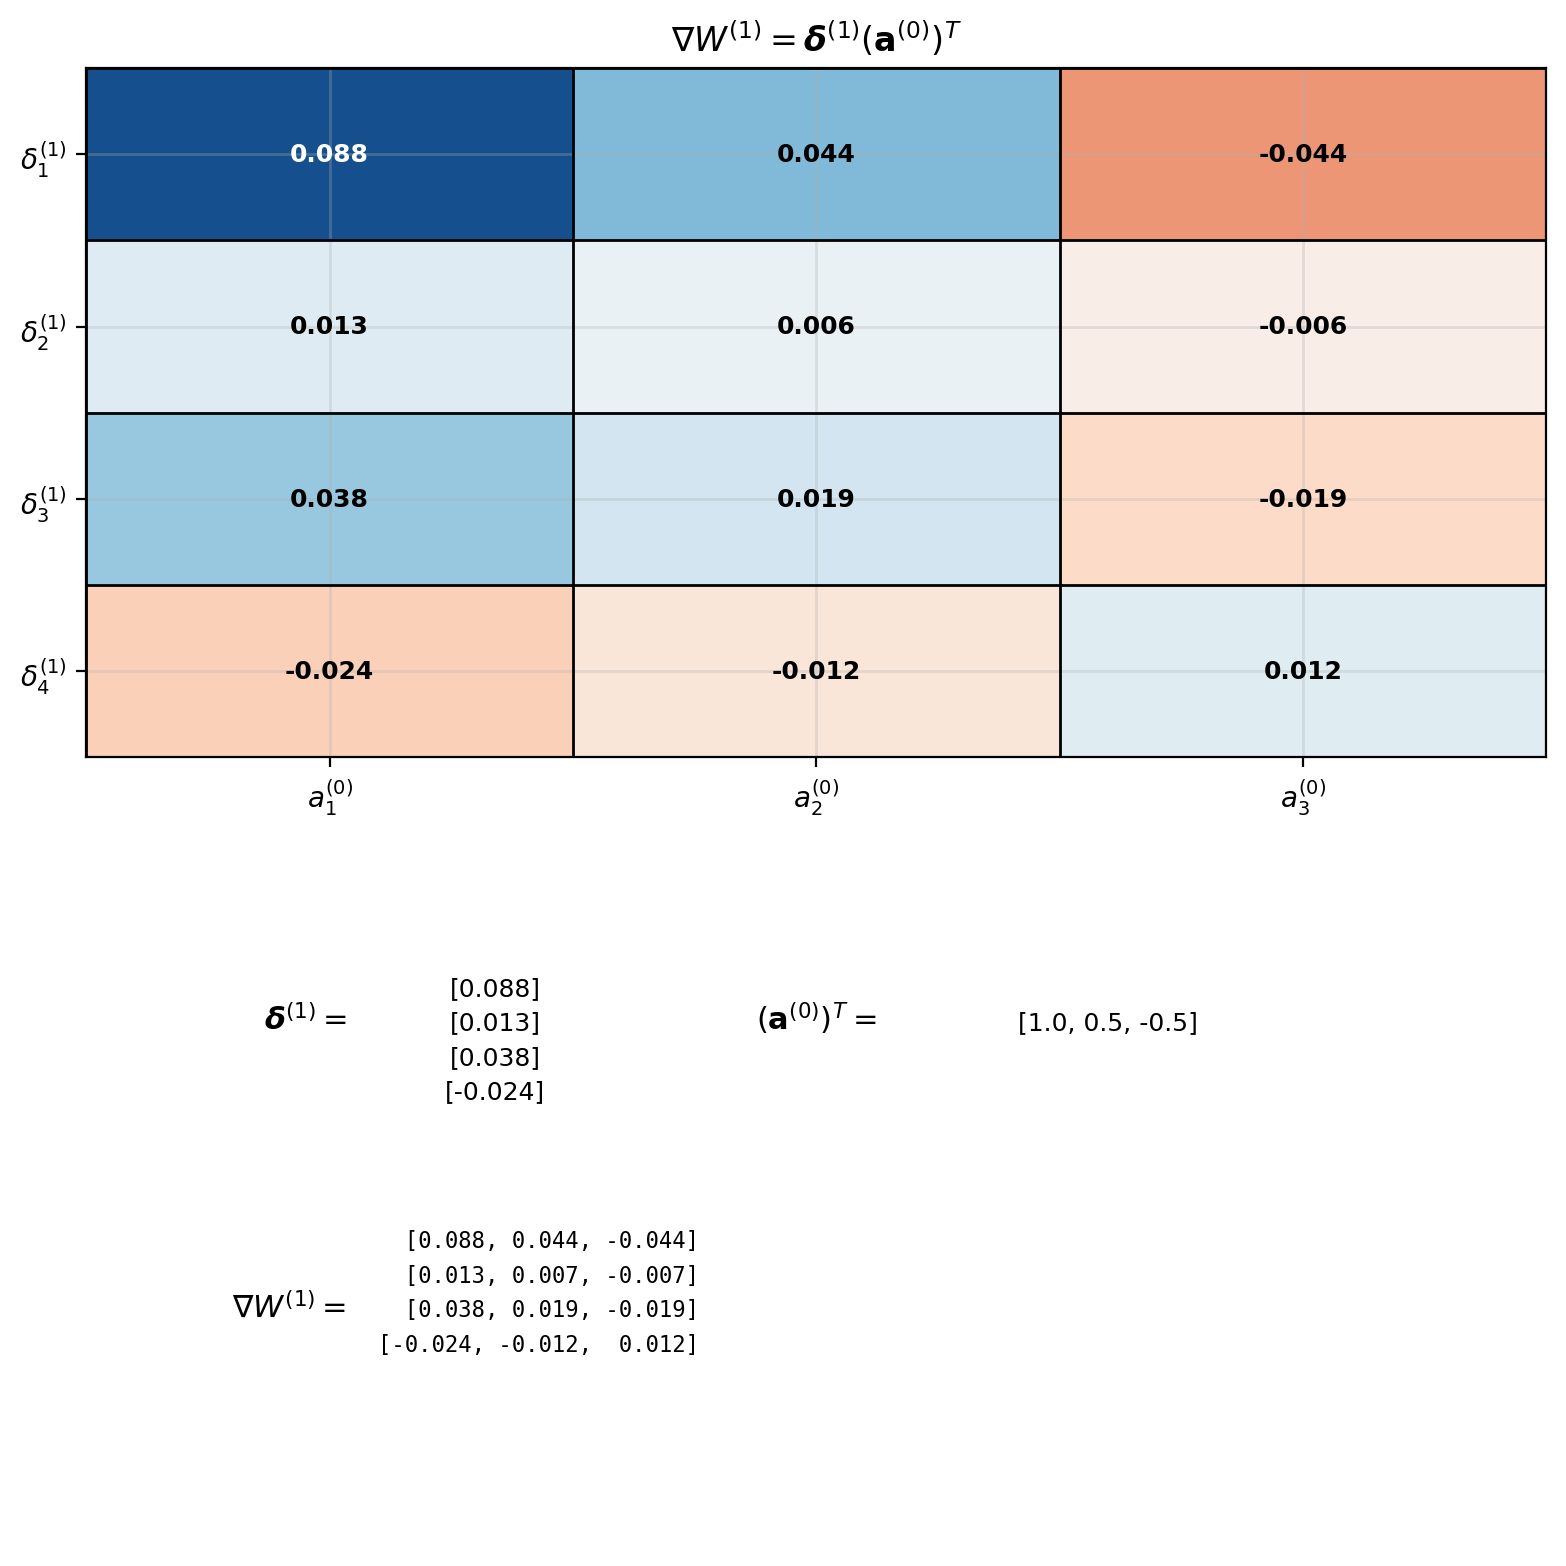
Layer written out: \(w_{ij}\) appears in row \(i\) and in no other row \[s_i = \sum_{j} w_{ij}\, a_j + b_i, \qquad \frac{\partial s_k}{\partial w_{ij}} = \begin{cases} a_j & k = i \\ 0 & k \neq i \end{cases}\]
Chain rule through the pre-activations: \(n_l\) terms, one nonzero \[\frac{\partial \ell}{\partial w_{ij}} = \sum_{k=1}^{n_l} \frac{\partial \ell}{\partial s_k}\, \frac{\partial s_k}{\partial w_{ij}} = \delta_1 \cdot 0 + \cdots + \delta_i\, a_j + \cdots + \delta_{n_l} \cdot 0 = \delta_i\, a_j\]
Example: \(w^{(2)}_{23}\), unit 2’s weight on \(a^{(1)}_3\)
- \(\delta^{(2)}_2 = -0.489\), \(\;a^{(1)}_3 = 0.463\)
- \(\partial \ell / \partial w^{(2)}_{23} = (-0.489)(0.463) = -0.226\)
Bias: \(\partial s_i / \partial b_i = 1\), so \(\partial \ell / \partial b_i = \delta_i\)
Same form as the scalar network: \(\delta^{(l)} a^{(l-1)}\), with the \(\delta\) of the unit the weight belongs to and the input it multiplies
Each Activation Affects Every Pre-Activation of the Next Layer
Layer written out: \(a_j\) multiplies one weight in every row, column \(j\) of \(\mathbf{W}\) \[s_i = \sum_{j} w_{ij}\, a_j + b_i, \qquad \frac{\partial s_i}{\partial a_j} = w_{ij} \;\text{ for every } i\]
Chain rule through the pre-activations: \(n_l\) terms, all nonzero, one per path to the loss \[\frac{\partial \ell}{\partial a_j} = \sum_{i=1}^{n_l} \frac{\partial \ell}{\partial s_i}\, \frac{\partial s_i}{\partial a_j} = \sum_{i=1}^{n_l} \delta_i\, w_{ij}\]
Example: \(a^{(1)}_1\) is an input to both output units, through \(w^{(2)}_{11} = 0.5\) and \(w^{(2)}_{21} = -0.2\) \[\frac{\partial \ell}{\partial a^{(1)}_1} = (0.489)(0.5) + (-0.489)(-0.2) = 0.342\]
Weights in the sum are column \(j\) of \(\mathbf{W}\): one input’s weights into every unit, where a row is one unit’s weights from every input
Branching rule of the scalar network: one product per branch, summed, with \(n_l\) branches
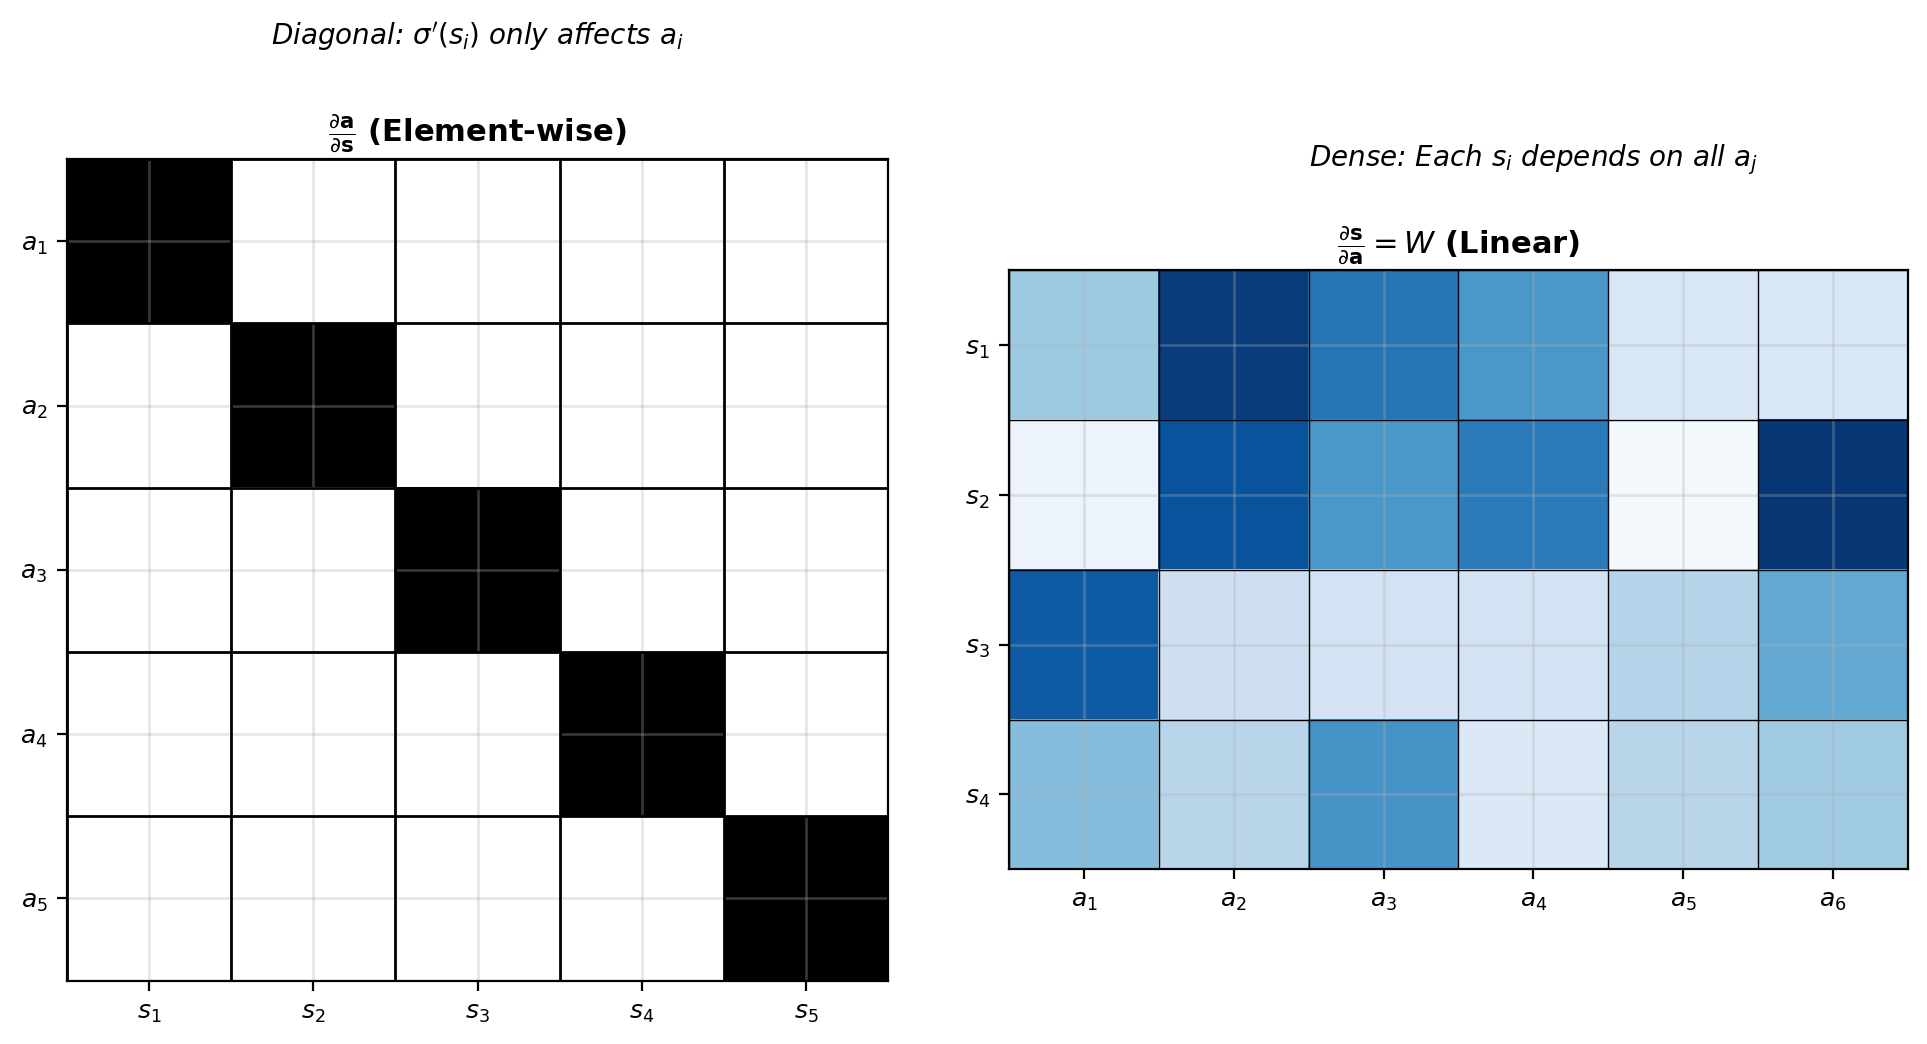
Element-Wise Activations Have Diagonal Jacobians
Activation written out: \(a_i = \sigma(s_i)\), with no other pre-activation in the expression \[\frac{\partial a_i}{\partial s_j} = \begin{cases} \sigma'(s_i) & j = i \\ 0 & j \neq i \end{cases}\]
Jacobian: the slopes on the diagonal, zeros elsewhere \[\frac{\partial \mathbf{a}^{(1)}}{\partial \mathbf{s}^{(1)}} = \mathrm{diag}\big(\sigma'(\mathbf{s}^{(1)})\big) = \begin{bmatrix} 0.242 & 0 & 0 & 0 \\ 0 & 0.250 & 0 & 0 \\ 0 & 0 & 0.249 & 0 \\ 0 & 0 & 0 & 0.222 \end{bmatrix}\]
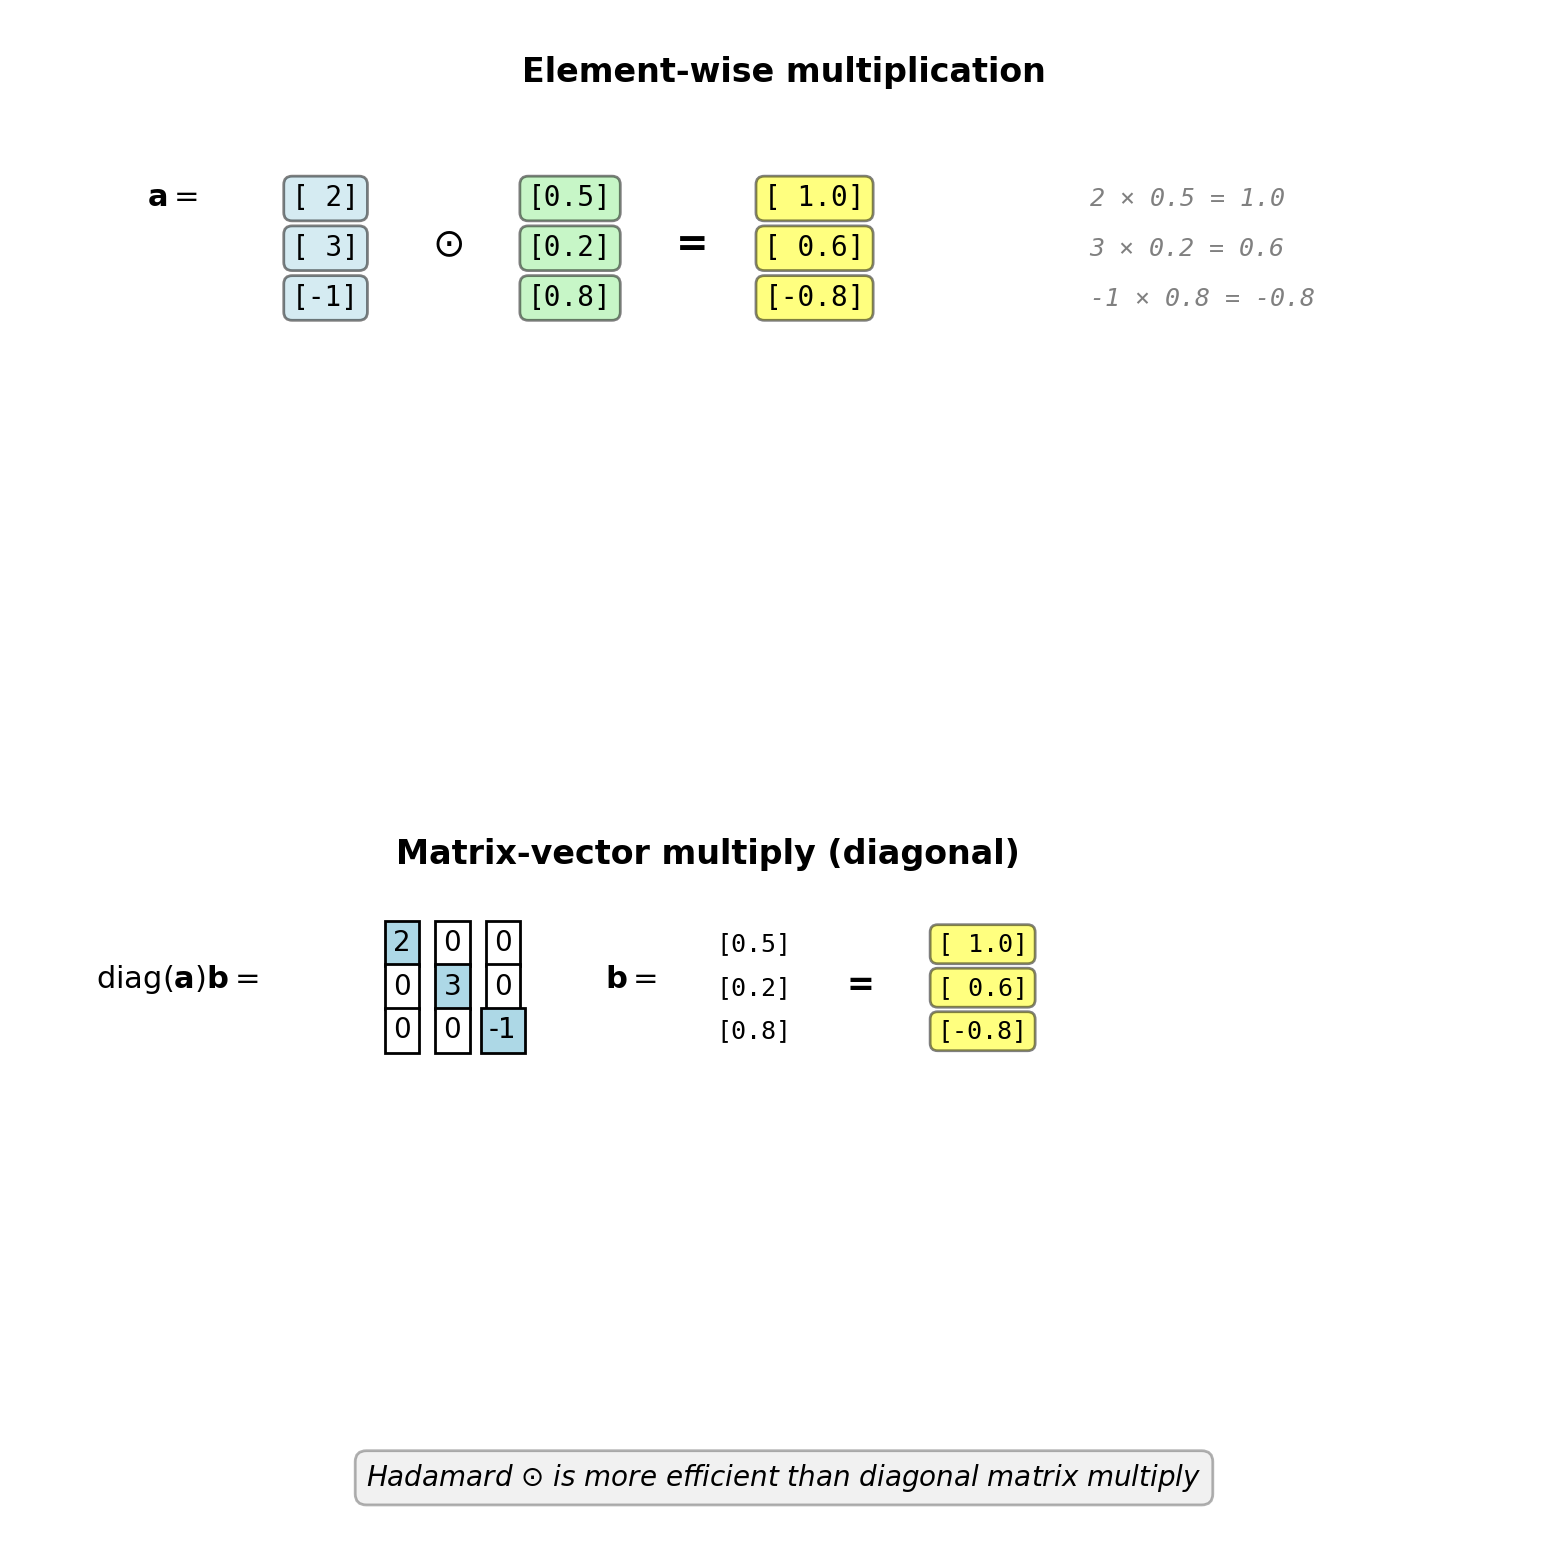
Chain rule: pre-multiply by the transpose, which for a diagonal matrix is the matrix itself \[\boldsymbol{\delta}^{(l)} = \Big(\frac{\partial \mathbf{a}^{(l)}}{\partial \mathbf{s}^{(l)}}\Big)^T \frac{\partial \ell}{\partial \mathbf{a}^{(l)}} = \mathrm{diag}\big(\sigma'(\mathbf{s}^{(l)})\big)\, \frac{\partial \ell}{\partial \mathbf{a}^{(l)}}\]
Example, entry 1 of the product: \(\;0.242 (0.342) + 0 (-0.342) + 0 (0.147) + 0 (-0.098) = 0.083\)
Sixteen products, twelve of them zero: each \(\delta_i\) is its own slope times its own \(\partial \ell / \partial a_i\)
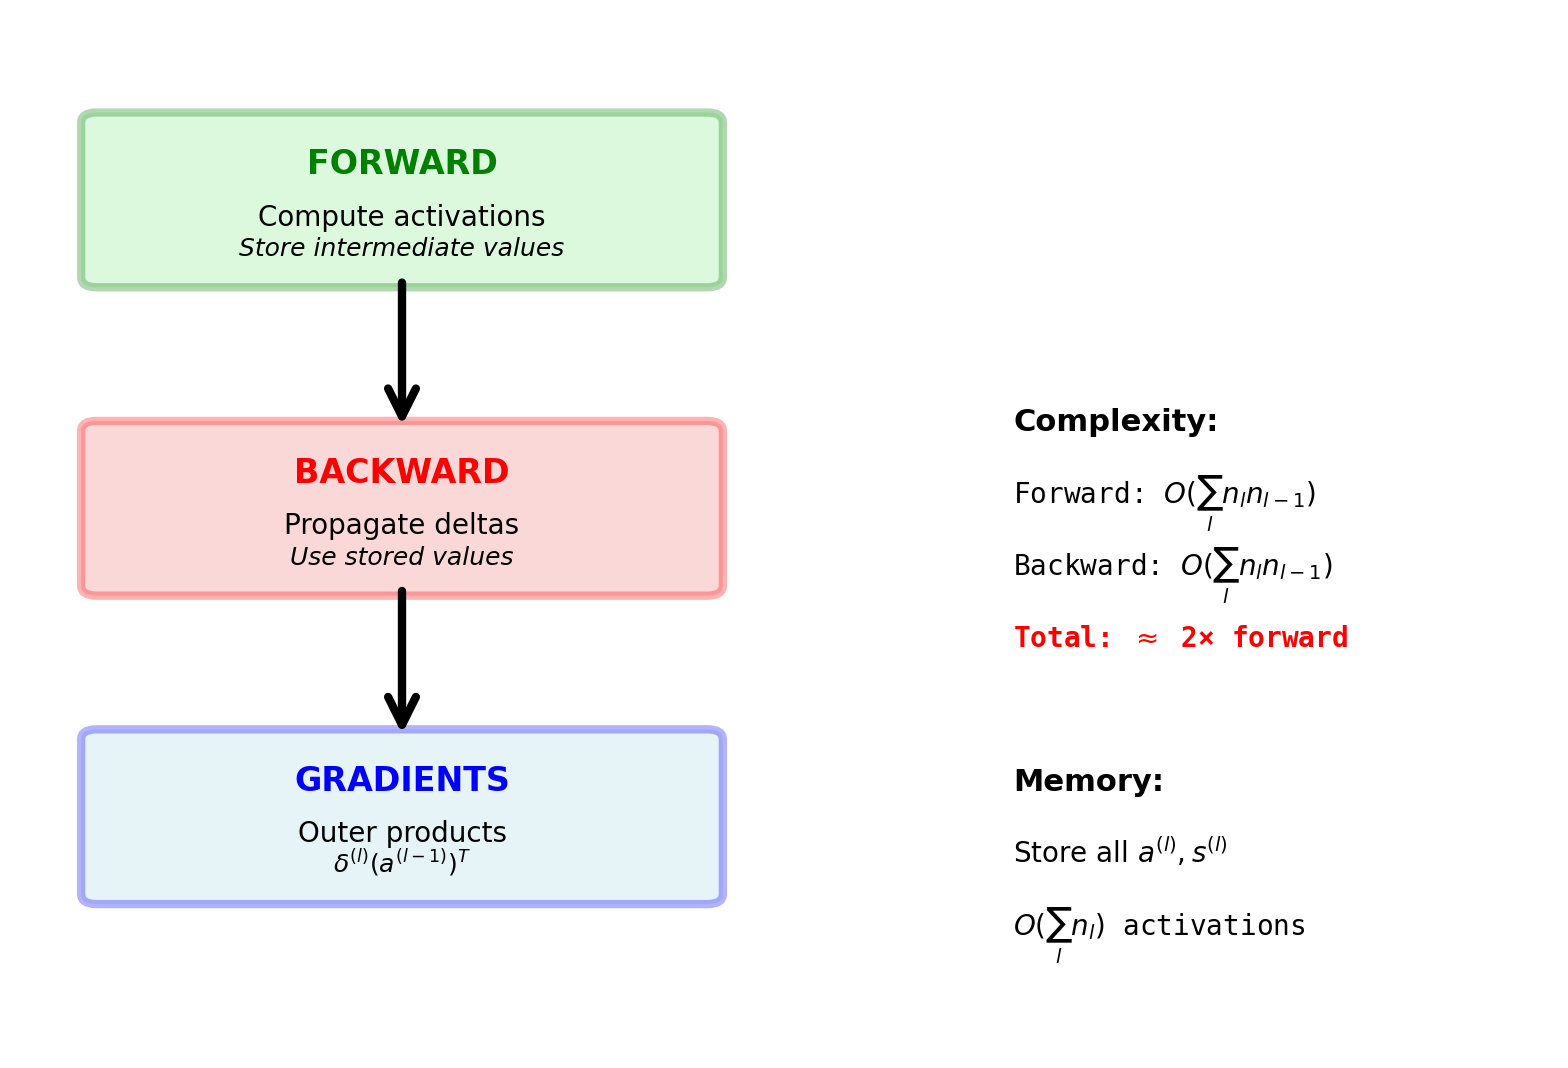
Backward Pass: Three Matrix Operations per Layer
Initialize: \(\;\boldsymbol{\delta}^{(L)} = \hat{\mathbf{y}} - \mathbf{y}\)
Propagate, \(l = L - 1, \ldots, 1\) \[\boldsymbol{\delta}^{(l)} = \big(\mathbf{W}^{(l+1)T} \boldsymbol{\delta}^{(l+1)}\big) \odot \sigma'(\mathbf{s}^{(l)})\]
Read off, \(l = L, \ldots, 1\) \[\frac{\partial \ell}{\partial \mathbf{W}^{(l)}} = \boldsymbol{\delta}^{(l)}\, \mathbf{a}^{(l-1)T}, \qquad \frac{\partial \ell}{\partial \mathbf{b}^{(l)}} = \boldsymbol{\delta}^{(l)}\]
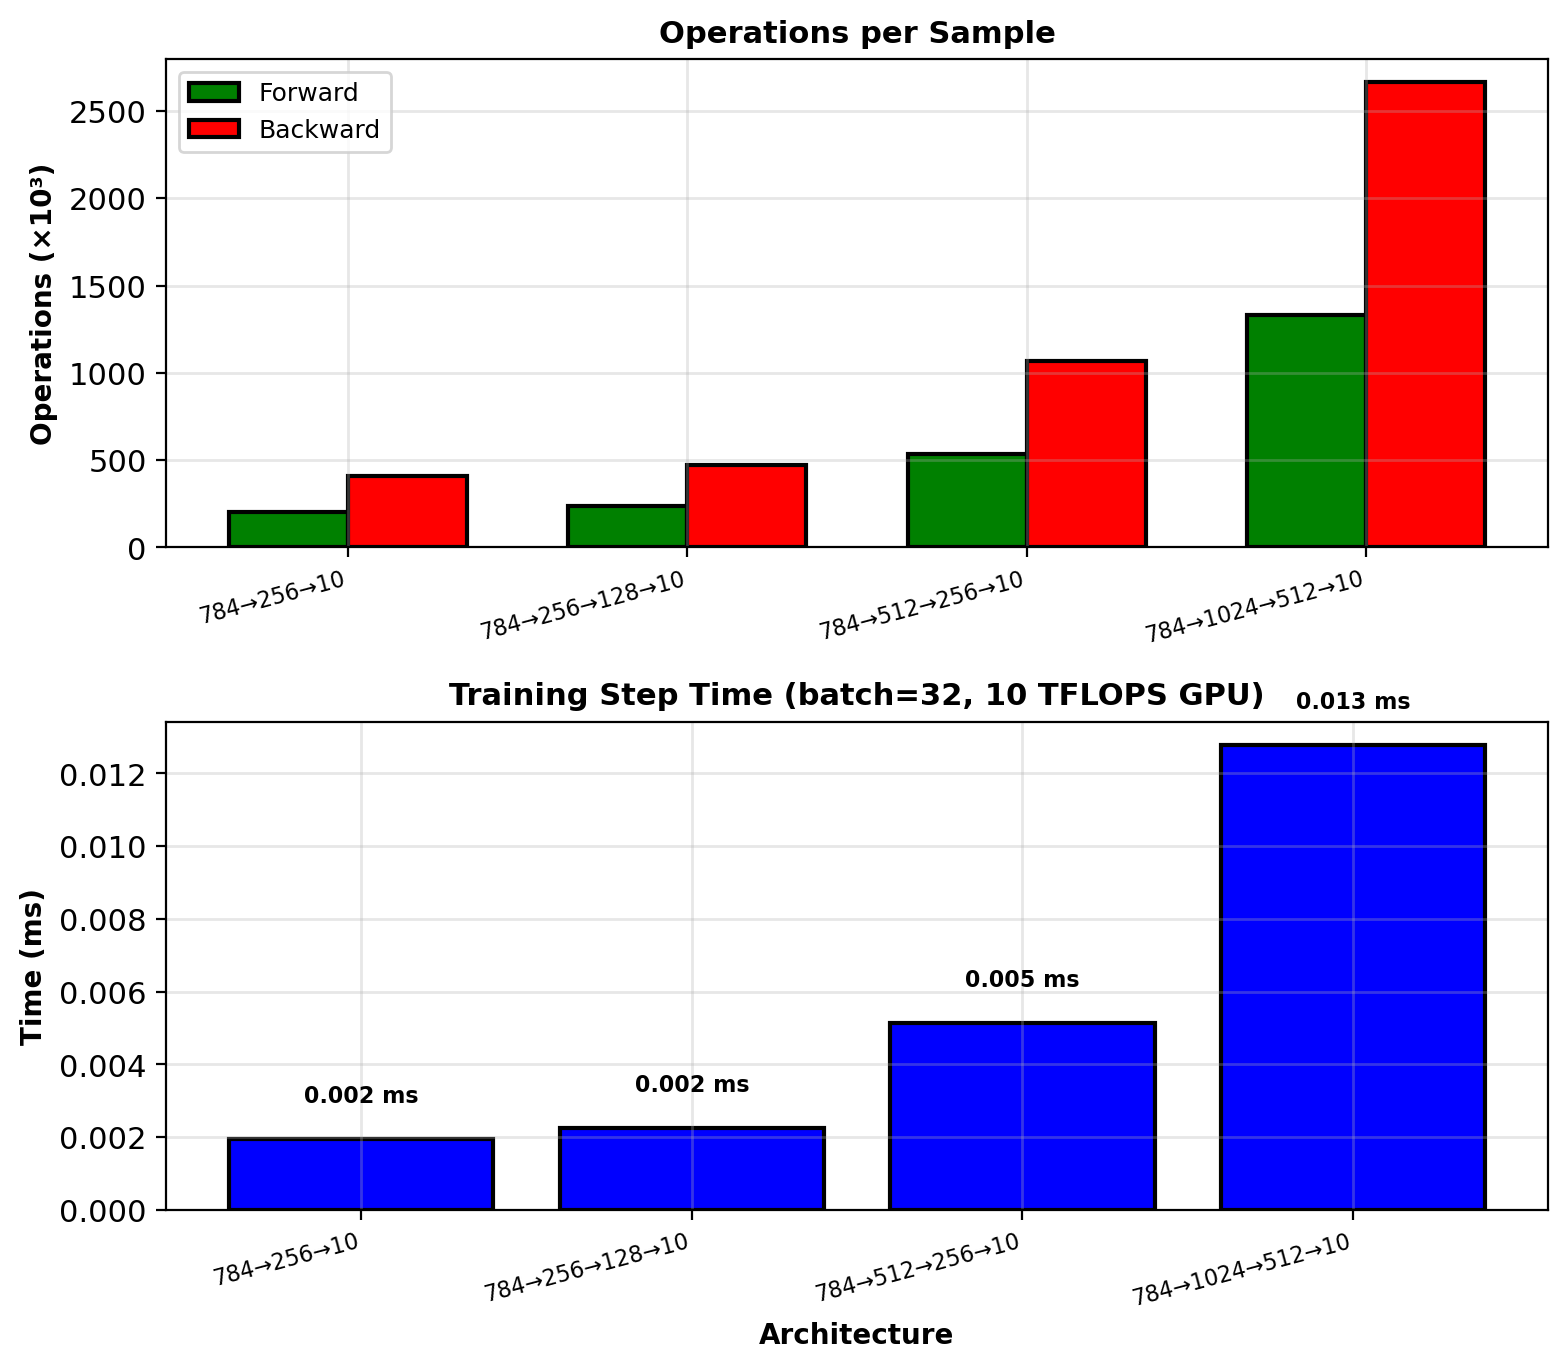
Multiplications per layer, against \(n_l n_{l-1}\) for its forward product
- Transpose product \(\mathbf{W}^{(l+1)T} \boldsymbol{\delta}^{(l+1)}\): \(\;n_l n_{l+1}\)
- Element-wise product: \(\;n_l\)
- Outer product \(\boldsymbol{\delta}^{(l)} \mathbf{a}^{(l-1)T}\): \(\;n_l n_{l-1}\)
3-4-2 network: hidden layer \(4 \cdot 2 + 4 + 4 \cdot 3 = 24\), output layer \(2 \cdot 4 = 8\), against \(20\) for the forward pass
Stored from the forward pass: \(\mathbf{a}^{(0)}, \ldots, \mathbf{a}^{(L-1)}\) for the outer products, \(\mathbf{s}^{(l)}\) or \(\mathbf{a}^{(l)}\) for the slopes
Mini-Batch Forward Pass: One Matrix Product per Layer
Objective over \(m\) samples: the mean loss, the empirical risk \[\mathcal{L} = \frac{1}{m} \sum_{i=1}^{m} \ell_i, \qquad \nabla \mathcal{L} = \frac{1}{m} \sum_{i=1}^{m} \nabla \ell_i\]
- A mean rather than a sum, so \(\eta\) means the same at every \(m\) Samples as rows: \(\mathbf{X} \in \mathbb{R}^{m \times d}\), row \(i\) equal to \(\mathbf{x}_i^T\), \(\;\mathbf{A}^{(0)} = \mathbf{X}\)
Forward pass for the batch: \(\mathbf{W}^T\) on the right, the bias added to every row \[\mathbf{S}^{(l)} = \mathbf{A}^{(l-1)} \mathbf{W}^{(l)T} + \mathbf{1}\, \mathbf{b}^{(l)T}, \qquad \mathbf{A}^{(l)} = \sigma(\mathbf{S}^{(l)})\]
- Shapes: \([m \times n_{l-1}][n_{l-1} \times n_l] = [m \times n_l]\)
- Row \(i\) of \(\mathbf{S}^{(l)}\): sample \(i\)’s \(\mathbf{s}^{(l)T}\), unchanged by the other rows
Row \(i\) of every matrix: sample \(i\), start to finish
Batch Gradient: \(\frac{1}{m}\, \boldsymbol{\Delta}^T \mathbf{A}\) Averages the Outer Products
Per sample: \(\boldsymbol{\delta}_i\, \mathbf{a}_i^T\), one outer product
Mean over the batch: one matrix product, the sum over \(i\) as its inner dimension \[\frac{\partial \mathcal{L}}{\partial \mathbf{W}^{(l)}} = \frac{1}{m} \sum_{i=1}^{m} \boldsymbol{\delta}_i^{(l)} \mathbf{a}_i^{(l-1)T} = \frac{1}{m}\, \boldsymbol{\Delta}^{(l)T} \mathbf{A}^{(l-1)}\] \[[n_l \times m][m \times n_{l-1}] = [n_l \times n_{l-1}]\]
Bias: the mean of the rows of \(\boldsymbol{\Delta}^{(l)}\) \[\frac{\partial \mathcal{L}}{\partial \mathbf{b}^{(l)}} = \frac{1}{m}\, \boldsymbol{\Delta}^{(l)T} \mathbf{1}\]
Three samples, output layer: column 1 of \(\boldsymbol{\Delta}^{(2)}\) against column 1 of \(\mathbf{A}^{(1)}\), \([0.587,\ 0.520,\ 0.540]^T\)
- Entry \((1, 1)\): \(\;\big(0.489 (0.587) - 0.522 (0.520) + 0.512 (0.540)\big) / 3 = 0.097\)
- \(\partial \mathcal{L} / \partial \mathbf{W}^{(2)}\) row 1: \(\;[0.097,\ 0.055,\ 0.082,\ 0.111]\), row 2 its negative
- \(\partial \mathcal{L} / \partial \mathbf{b}^{(2)} = [0.160,\ -0.160]^T\)
Same shape as \(\mathbf{W}^{(l)}\): \(n_l \times n_{l-1}\), whatever \(m\) is
Backpropagation Propagates Gradients, Not Errors
Propagated: \(\boldsymbol{\delta}^{(l)} = \partial \ell / \partial \mathbf{s}^{(l)}\), the gradient of the loss with respect to layer \(l\)’s pre-activations
| Layer | Target | \(\boldsymbol{\delta}\) |
|---|---|---|
| Output | \(\mathbf{y}\) | \(\hat{\mathbf{y}} - \mathbf{y}\) under cross-entropy |
| Hidden | none | \(\big(\mathbf{W}^{(l+1)T} \boldsymbol{\delta}^{(l+1)}\big) \odot \sigma'(\mathbf{s}^{(l)})\) |
- 3-4-2 network: \(\boldsymbol{\delta}^{(2)} = [0.489,\ -0.489]^T\), \(\;\boldsymbol{\delta}^{(1)} = [0.083,\ -0.086,\ 0.036,\ -0.022]^T\)
Output pairings with \(\boldsymbol{\delta}^{(L)} = \hat{\mathbf{y}} - \mathbf{y}\)
- Sigmoid with cross-entropy
- Softmax with cross-entropy
- Linear output with squared loss
Sigmoid with squared loss: \(\;\delta^{(L)} = (\hat{y} - y)\, \hat{y}(1 - \hat{y})\), the error times the slope
Hidden \(\boldsymbol{\delta}\): either sign, any size, no target for \(\mathbf{a}^{(l)}\)
“Learning representations by back-propagating errors”, Rumelhart, Hinton, and Williams, 1986
- The propagated quantity there: \(\partial \ell / \partial \mathbf{s}^{(l)}\), called the error signal
Every parameter’s gradient is one chain rule: \(\partial \ell / \partial w_{ij} = \delta_i\, a_j\)
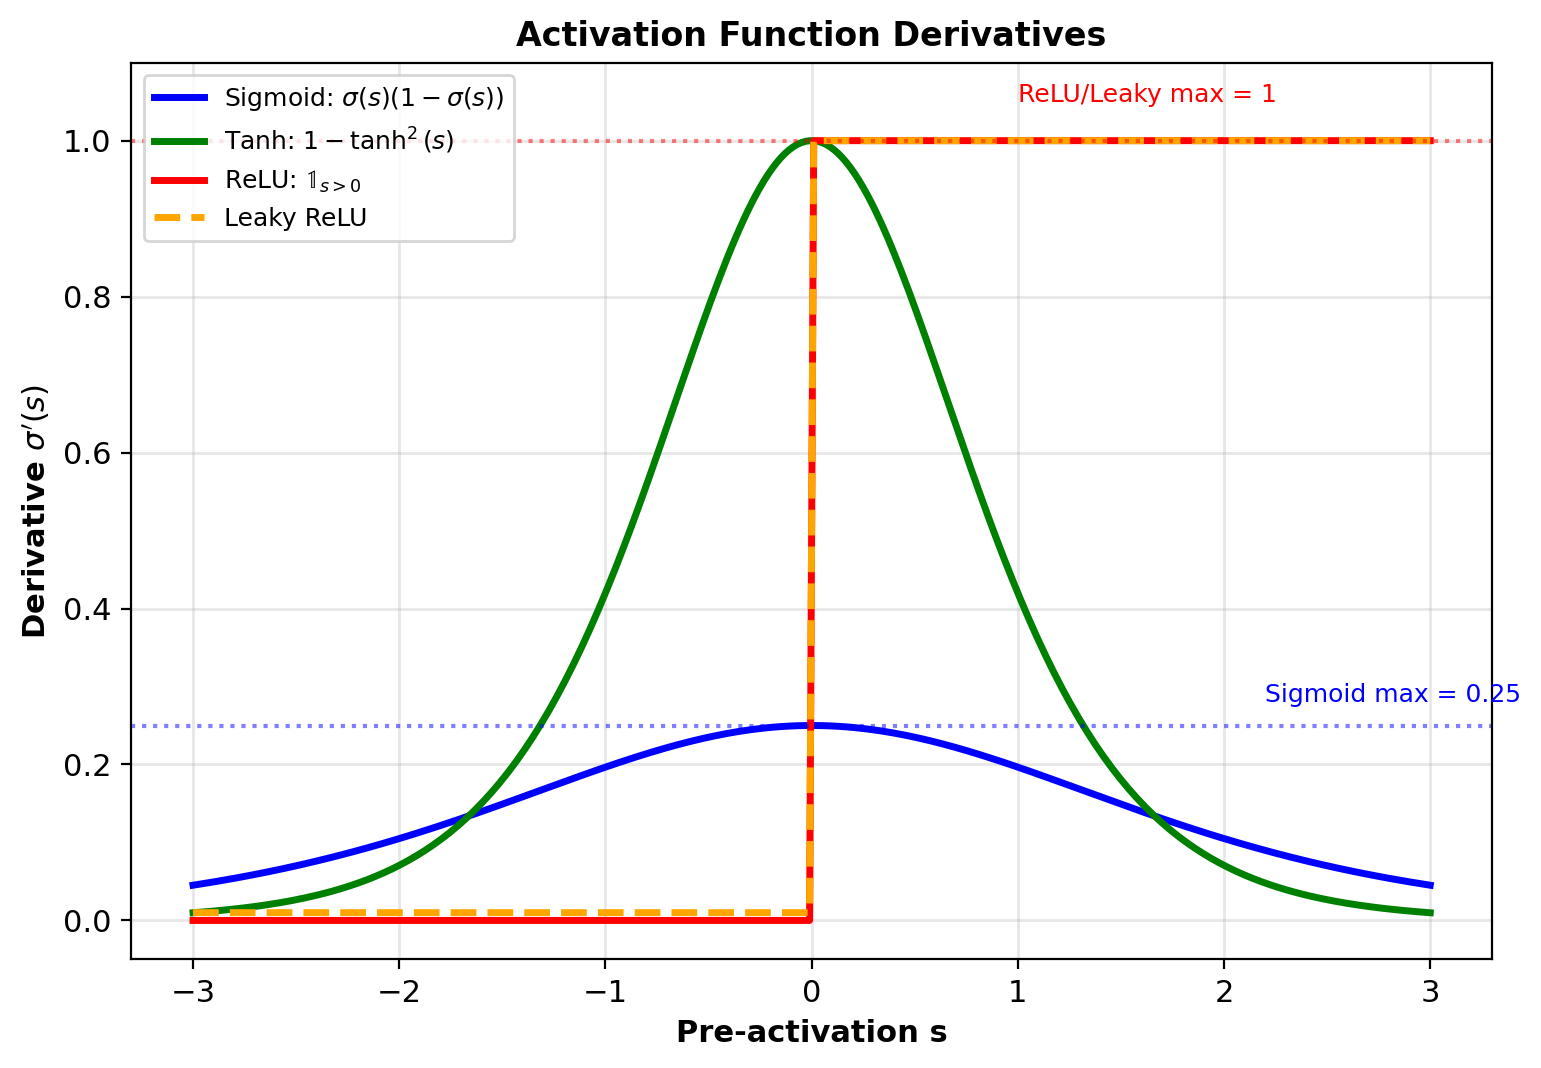
Only the Slope \(\sigma'\) of an Activation Appears in the Backward Pass
In the loops: \(\sigma^{(l)}\) once in the forward pass, \(\sigma'(\mathbf{s}^{(l)})\) once in the backward pass, nowhere else
| Activation | \(\sigma(s)\) | \(\sigma'(s)\) | From \(a\) | Max slope |
|---|---|---|---|---|
| Sigmoid | \(1 / (1 + e^{-s})\) | \(\sigma(s)(1 - \sigma(s))\) | \(a(1 - a)\) | \(1/4\), at \(s = 0\) |
| Tanh | \(\tanh s\) | \(1 - \tanh^2 s\) | \(1 - a^2\) | \(1\), at \(s = 0\) |
| ReLU | \(\max(s, 0)\) | \(\mathbb{1}[s > 0]\) | \(\mathbb{1}[a > 0]\) | \(1\), for every \(s > 0\) |
Stored per layer: \(\mathbf{a}^{(l)}\) alone
Changing the activation: new numbers in \(\sigma'(\mathbf{s}^{(l)})\), the same three loops
Sigmoid slope: \(0.045\) at \(s = 3\) and \(0.0066\) at \(s = 5\)
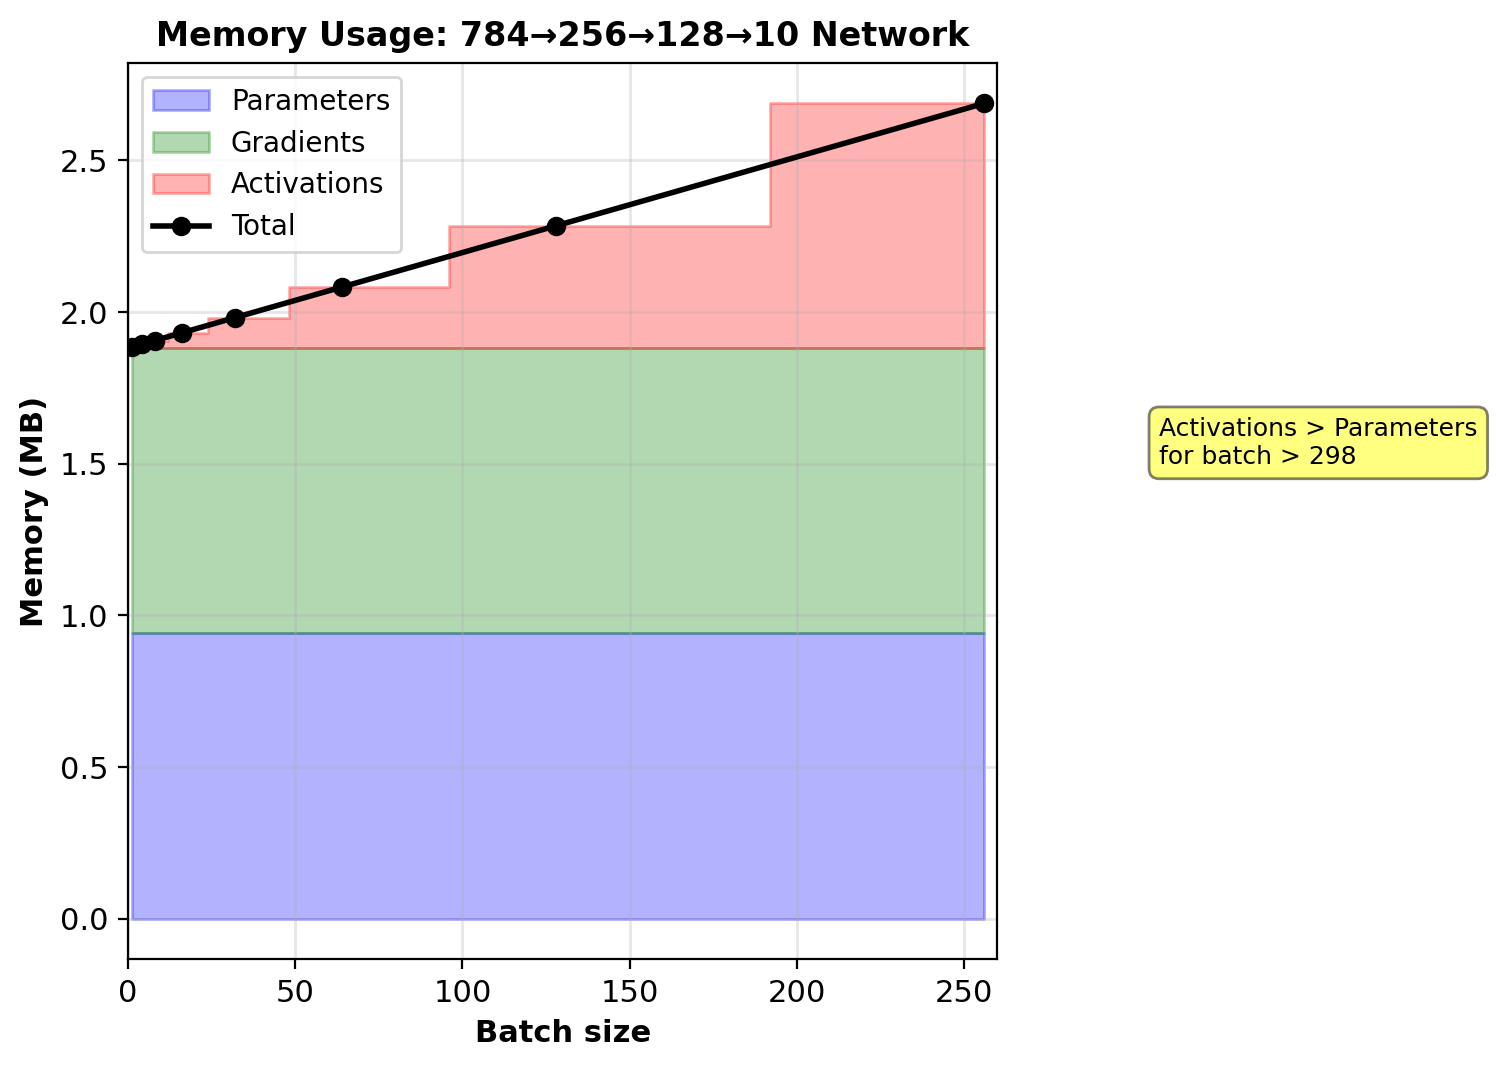
Memory per Training Step Is Linear in the Batch Size
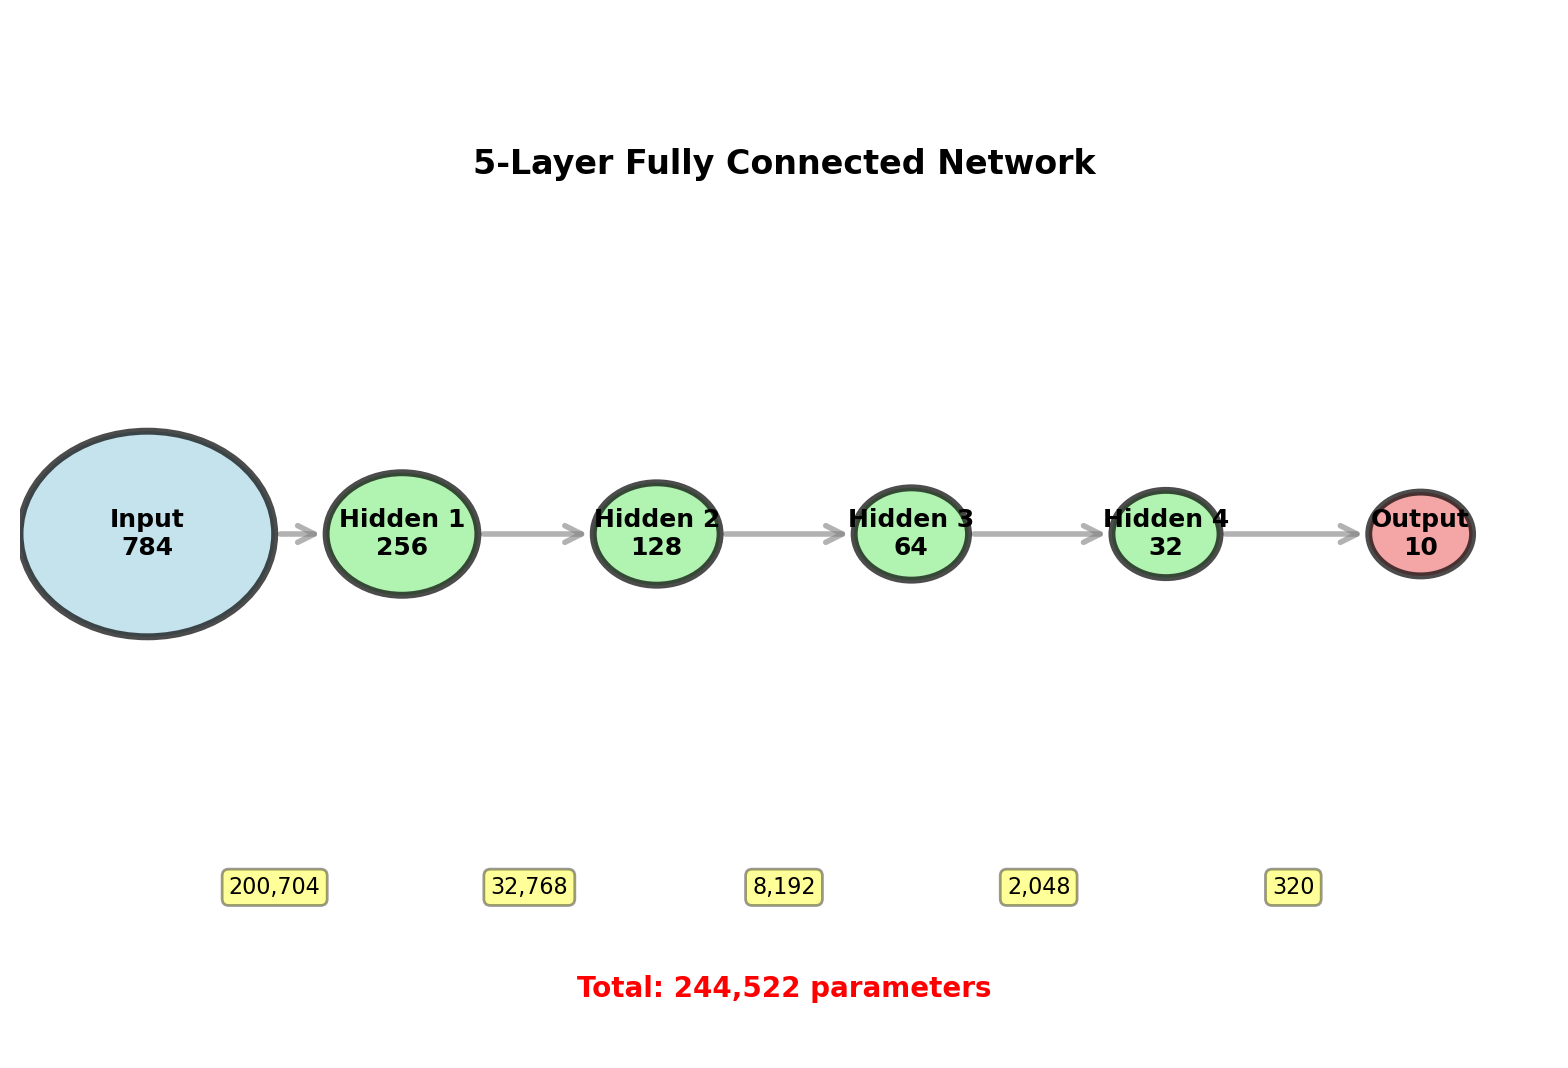
Held through one step, float32, layers of 784, 256, 128, and 10 units
| Array | Values | Size | Held until |
|---|---|---|---|
| Parameters | \(235{,}146\) | \(0.94\) MB | always |
| Gradients | \(235{,}146\) | \(0.94\) MB | the update |
| \(\mathbf{a}^{(0)}, \ldots, \mathbf{a}^{(L)}\) | \(1{,}178\) per sample | \(4.7\) KB per sample | the backward pass |
Per step: \(\;1.88 \text{ MB} + 4.7 \text{ KB} \times m\)
- \(m = 32\): \(2.03\) MB
- \(m = 1024\): \(6.71\) MB
Largest batch in a budget: \(m \le (\text{budget} - 1.88 \text{ MB}) / 4.7 \text{ KB}\), \(\;1{,}298\) in \(8\) MB
Inference stores no gradients and one layer’s activations at a time: the batch size is a training cost
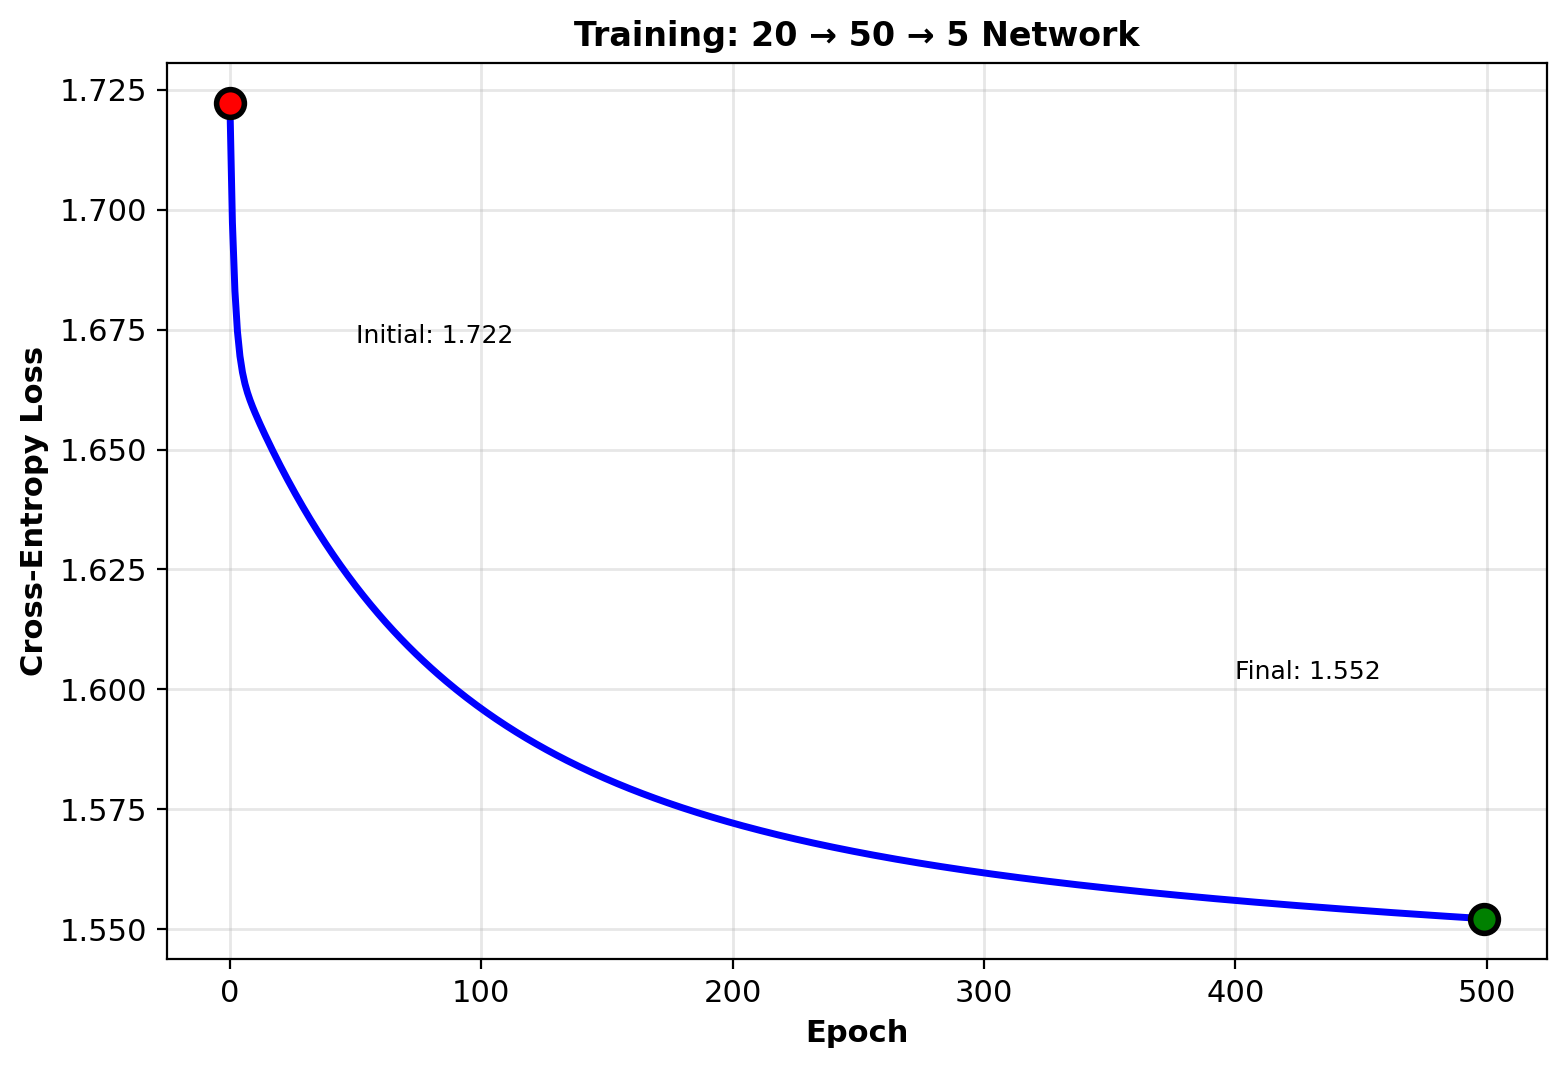
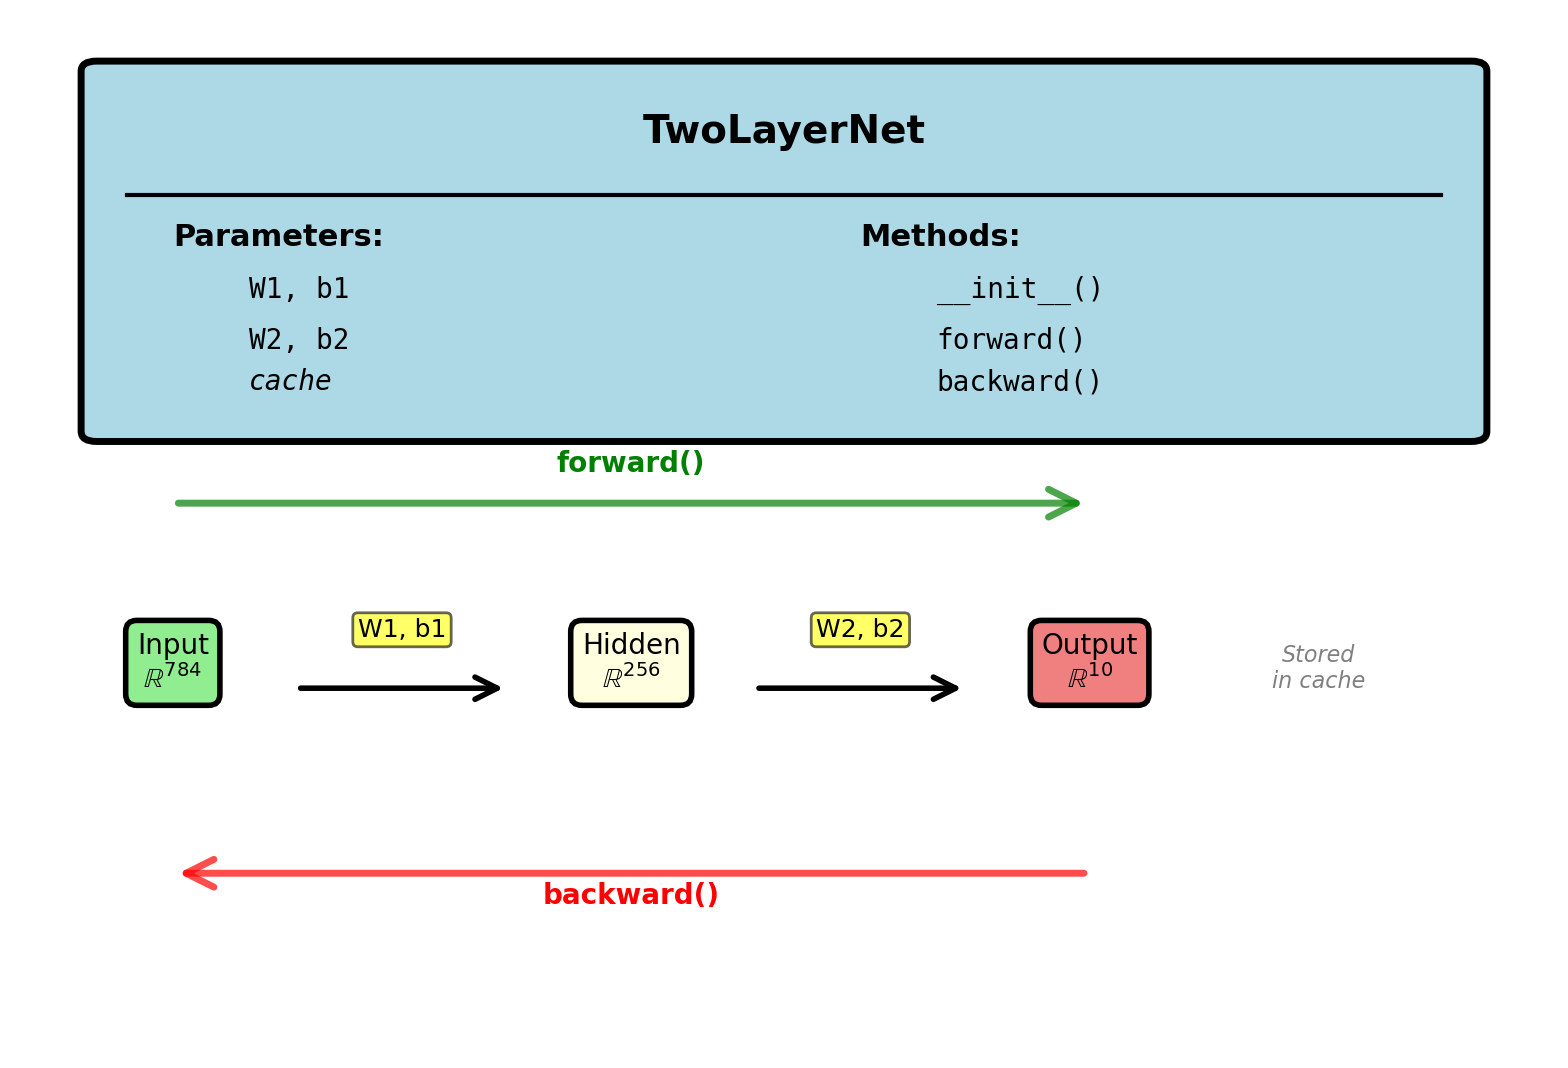
Networks Are Directed Acyclic Graphs of Operations
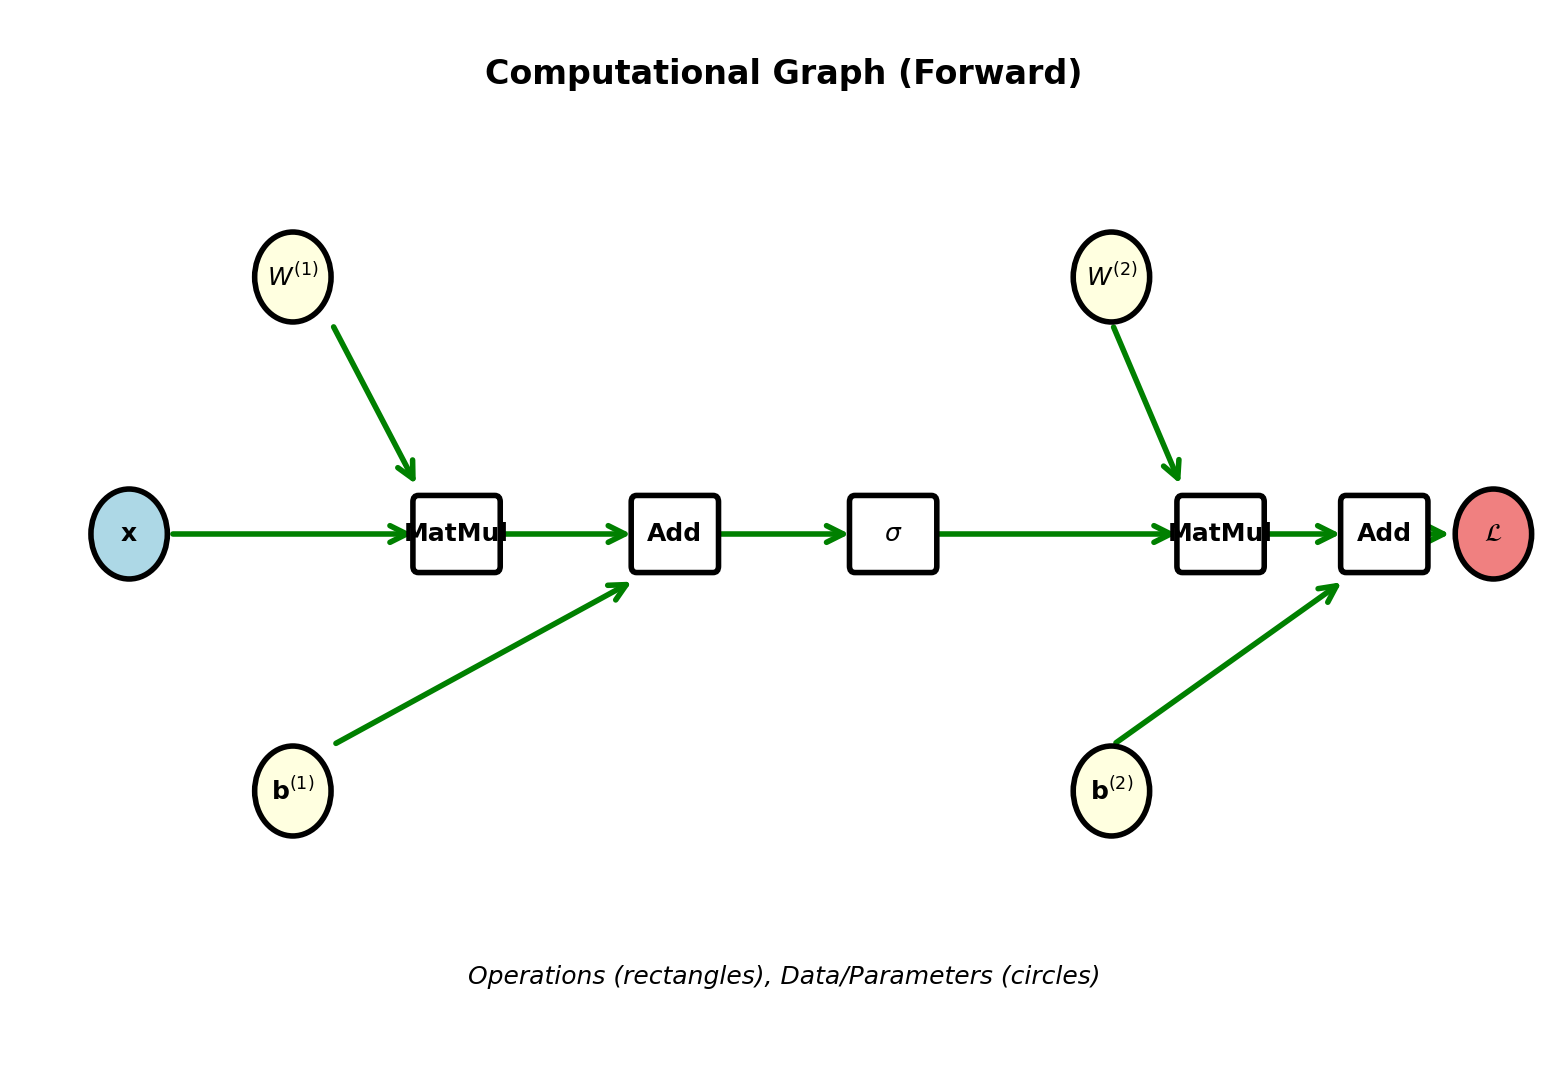
Computational graph: nodes are operations, edges the arrays between them
- Directed: an edge runs from the operation that produces an array to each operation that uses it
- Acyclic: no array depends on itself, so the nodes have a topological order, every node after the nodes it uses
Forward pass: the nodes in a topological order, each from the outputs of the nodes before it
Backward pass: the same nodes in the reverse order, each from the gradient of the node after it
3-4-2 network: a chain of seven nodes with \(26\) parameters at two of them
- A layer is three nodes: multiply, add, activate
Cycle would leave no order: a recurrent connection is unrolled in time into a DAG before either pass runs
Each Node Implements a Forward Call and a Backward Call
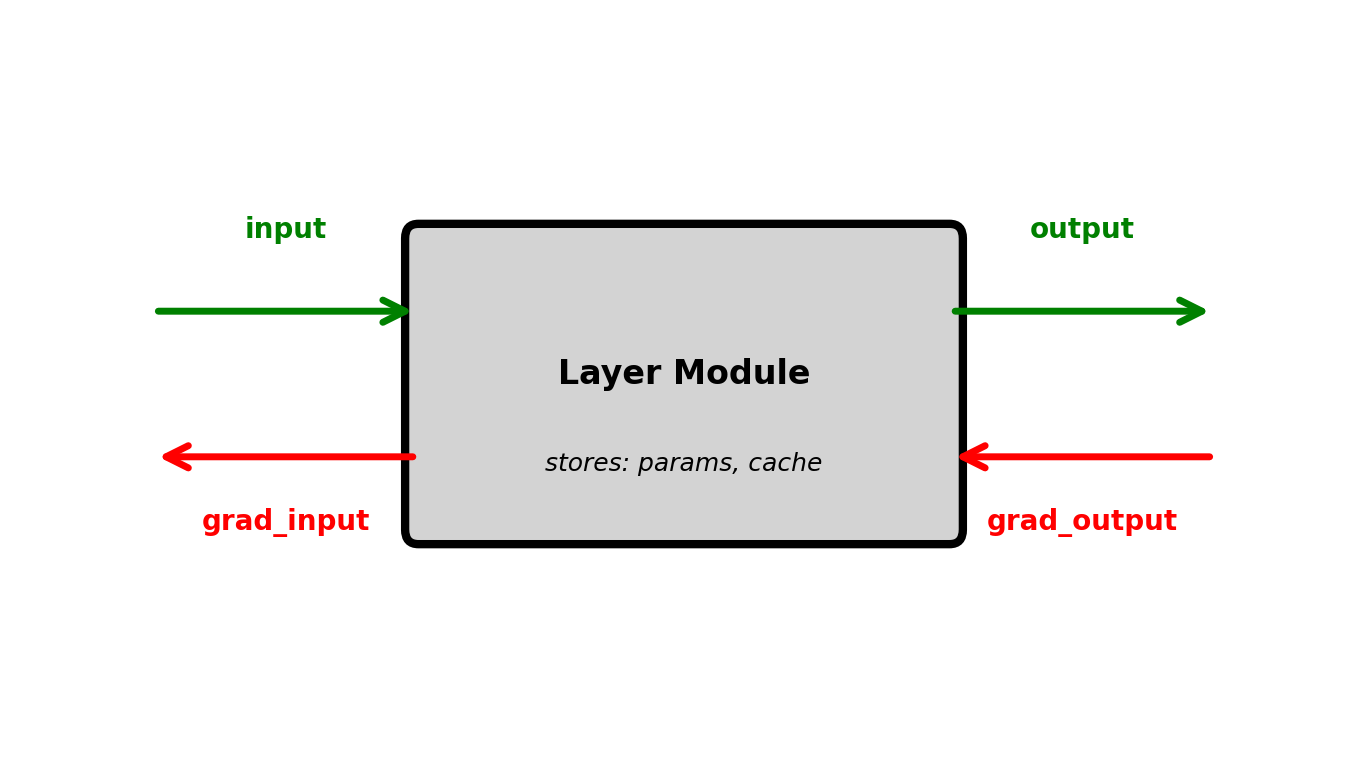
Forward call: inputs in, output out, and the values its Jacobian is evaluated at stored
Backward call: the gradient at its output in, one gradient per input out \[\frac{\partial \ell}{\partial \mathbf{u}} = \Big(\frac{\partial \mathbf{v}}{\partial \mathbf{u}}\Big)^T \frac{\partial \ell}{\partial \mathbf{v}}\]
Multiply node, \(\mathbf{s} = \mathbf{W}\mathbf{a}\)
forward(W, a):
    keep W, a
    return W a
backward(g):
    return  g aᵀ  to W
            Wᵀ g  to a
Chain rule as composition: the backward calls in reverse order, each from the previous one’s result
- Multiply by \(\mathbf{W}^{(2)}\): \(\partial \ell / \partial \mathbf{a}^{(1)}\) from \(\boldsymbol{\delta}^{(2)}\)
- Then \(\sigma\): \(\boldsymbol{\delta}^{(1)}\) from \(\partial \ell / \partial \mathbf{a}^{(1)}\)
- The layer recursion is these two calls
Output layer’s multiply node, backward call with \(\boldsymbol{\delta}^{(2)} = [0.489,\ -0.489]^T\) in and \(\mathbf{a}^{(1)} = [0.587,\ 0.512,\ 0.463,\ 0.668]^T\) stored
- To \(\mathbf{a}^{(1)}\): \(\;\mathbf{W}^{(2)T} \boldsymbol{\delta}^{(2)} = [0.342,\ -0.342,\ 0.147,\ -0.098]^T\)
- To \(\mathbf{W}^{(2)}\): \(\;\boldsymbol{\delta}^{(2)} \mathbf{a}^{(1)T}\), first row \([0.287,\ 0.251,\ 0.226,\ 0.327]\)
No derivation per network: a new graph of the same nodes has its backward pass from the same calls, in its own reverse order
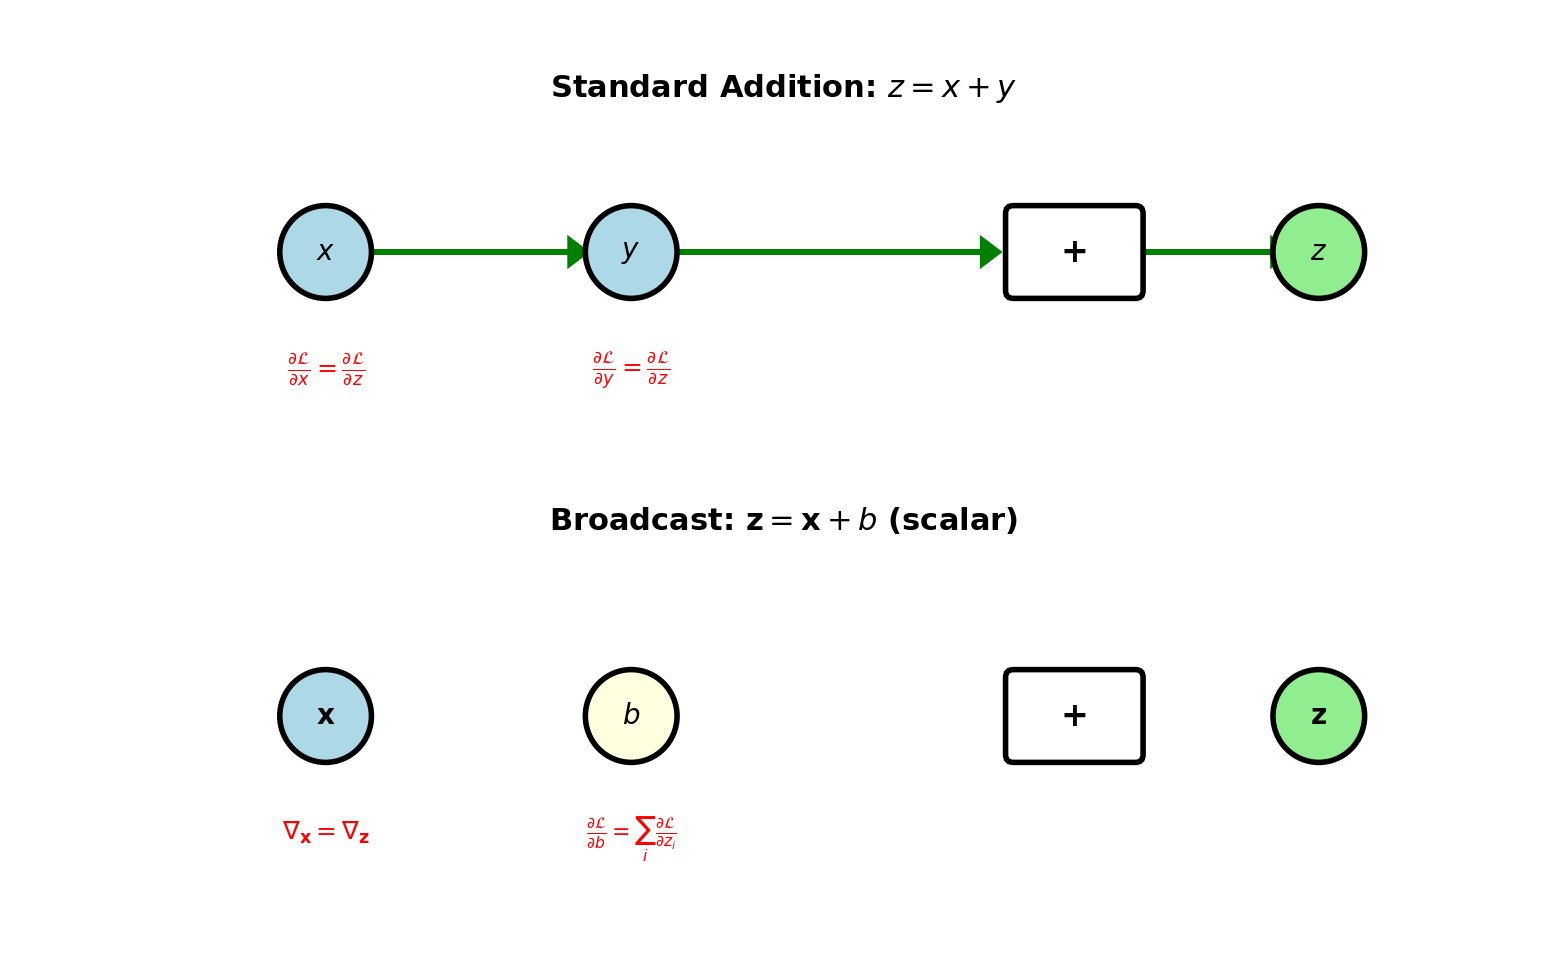
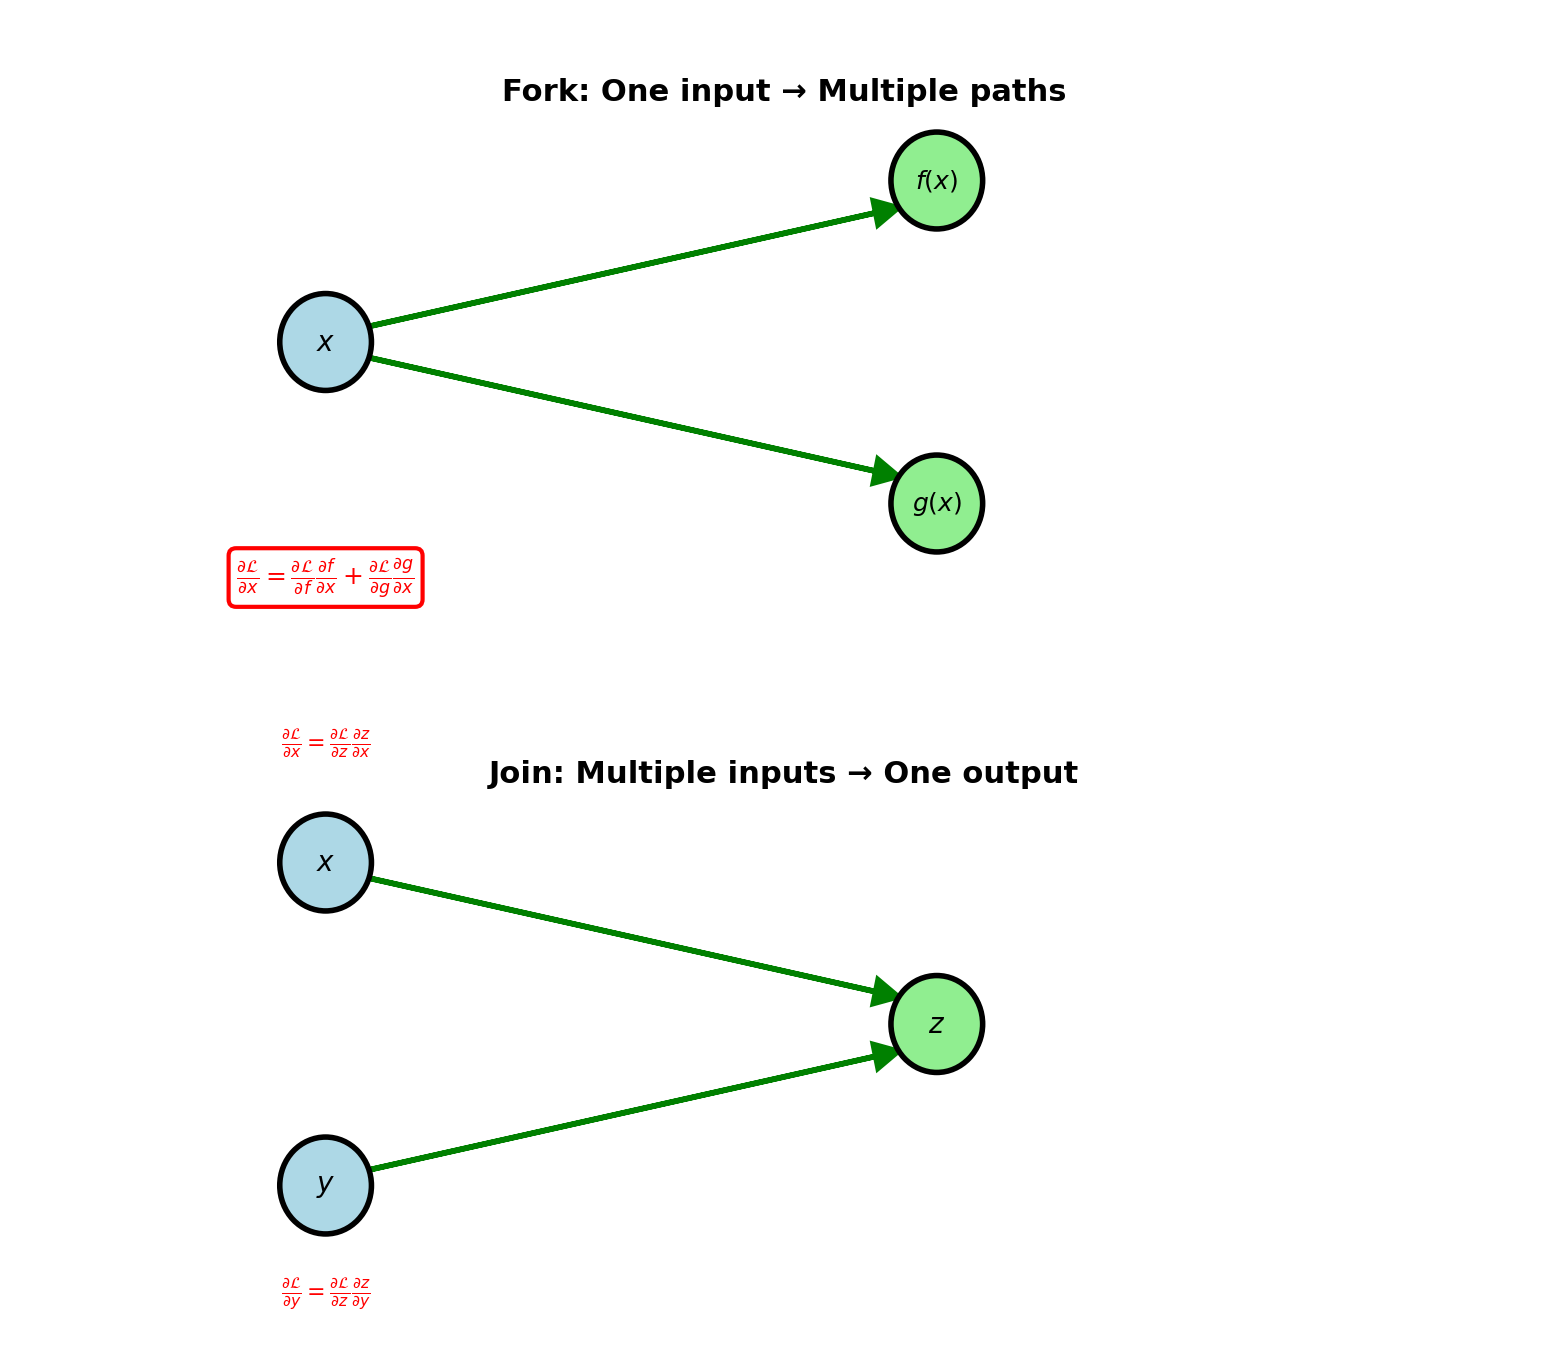
Gradients Add Where a Value Is Reused
Fork: a value \(\mathbf{a}\) used by \(k\) nodes has \(k\) gradients, one per path, summed \[\frac{\partial \ell}{\partial \mathbf{a}} = \sum_{j=1}^{k} \mathbf{J}_j^T\, \frac{\partial \ell}{\partial \mathbf{v}_j}\]
- Hidden activation into \(n_{l+1}\) units: \(n_{l+1}\) terms, which is \(\mathbf{W}^{(l+1)T} \boldsymbol{\delta}^{(l+1)}\)
- Bias added to every row of a batch: \(m\) terms, which is \(\boldsymbol{\Delta}^{(l)T} \mathbf{1}\)
- Shortcut \(\mathbf{y} = \mathbf{x} + f(\mathbf{x})\): \(\;\partial \ell / \partial \mathbf{x} = \partial \ell / \partial \mathbf{y} + \mathbf{J}_f^T\, \partial \ell / \partial \mathbf{y}\)
g[a] = 0
for each node j that uses a:
g[a] += Jⱼᵀ g[vⱼ]Join: a node with several inputs gives each its own gradient, as the multiply node gives \(\mathbf{W}\) and \(\mathbf{a}\) theirs
Two-path chain rule, for any graph: one product per path, products added
Shortcut’s first term has no slope and no weight in it: \(\partial \ell / \partial \mathbf{y}\) is added to \(\partial \ell / \partial \mathbf{x}\) unchanged, whatever \(f\) does to the second term
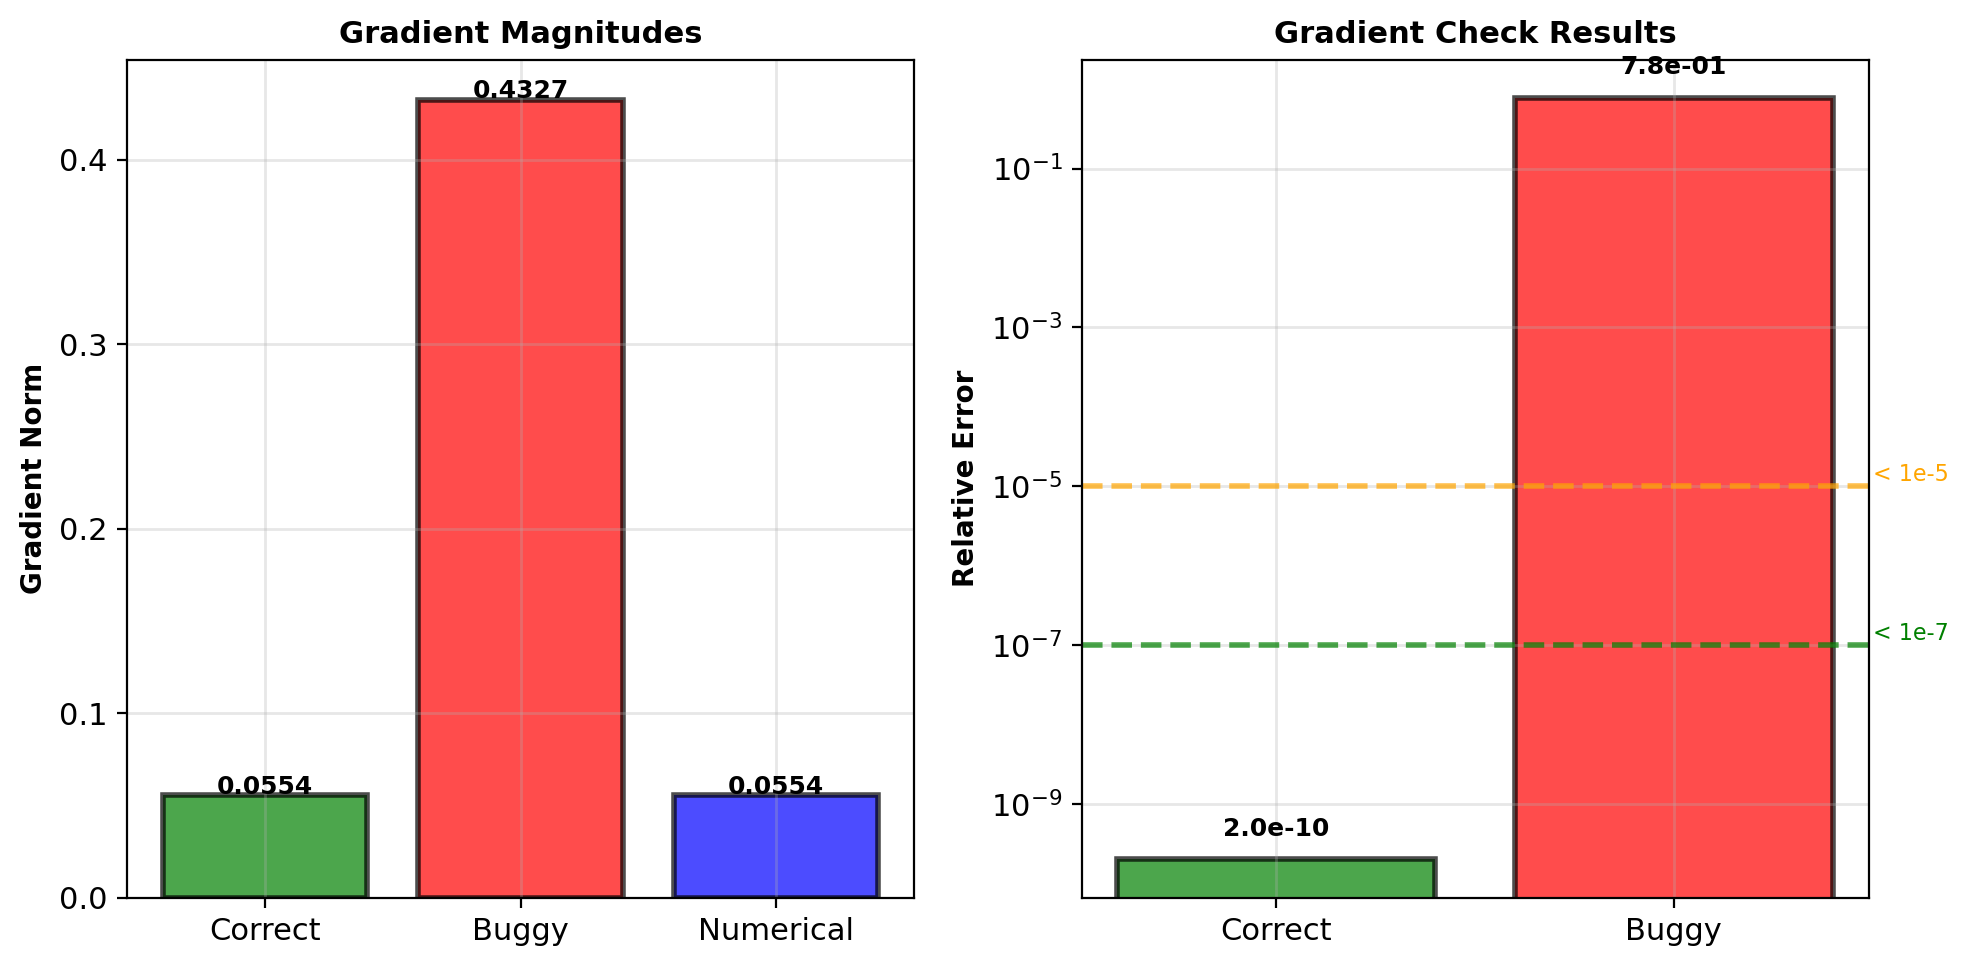
Finite Differences Check the Backward Pass Against the Loss Itself
Centered difference, one parameter at a time, from the forward pass alone \[\frac{\partial \mathcal{L}}{\partial w} \approx \frac{\mathcal{L}(w + \epsilon) - \mathcal{L}(w - \epsilon)}{2\epsilon}\]
Relative error between the backward pass’s gradient \(\mathbf{g}\) and the difference gradient \(\mathbf{g}_\epsilon\) \[\frac{\|\mathbf{g} - \mathbf{g}_\epsilon\|}{\|\mathbf{g}\| + \|\mathbf{g}_\epsilon\|}\]
Truncation, the \(\epsilon^2\) terms dropped from the Taylor expansion
- \(1.4 \times 10^{-4}\) at \(\epsilon = 10^{-1}\), \(\;1.4 \times 10^{-6}\) at \(10^{-2}\)
Roundoff, two nearly equal losses each exact to \(u = 1.1 \times 10^{-16}\), their difference divided by \(2\epsilon\)
- Grows as \(1/\epsilon\): about \(10^{-6}\) at \(10^{-9}\), \(10^{-3}\) at \(10^{-12}\)
Floor: about \(10^{-10}\) at \(\epsilon = 10^{-5}\) on the 3-4-2 batch, in double precision
Cost: two forward passes per parameter checked
- A small network, or a sample of entries
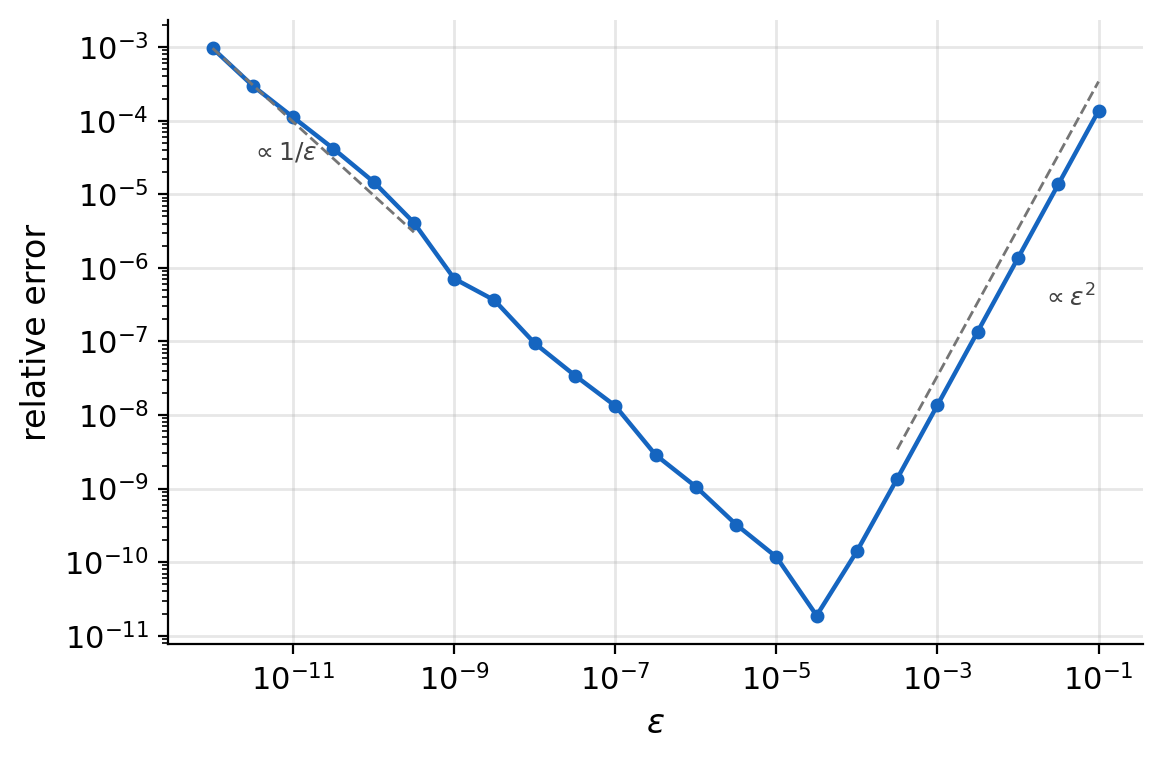
Agreement: an error near the floor, \(10^{-10}\) to \(10^{-8}\) at \(\epsilon = 10^{-5}\) in double precision
- A wrong backward pass is off by orders of magnitude, so the band need not be exact
Missing Factors Show as Errors of Order One
One line wrong: the sigmoid slope left out of \(\boldsymbol{\Delta}^{(1)}\)
D1 = D2 @ W2                        slope missing
D1 = (D2 @ W2) * A1 * (1 - A1)      correct
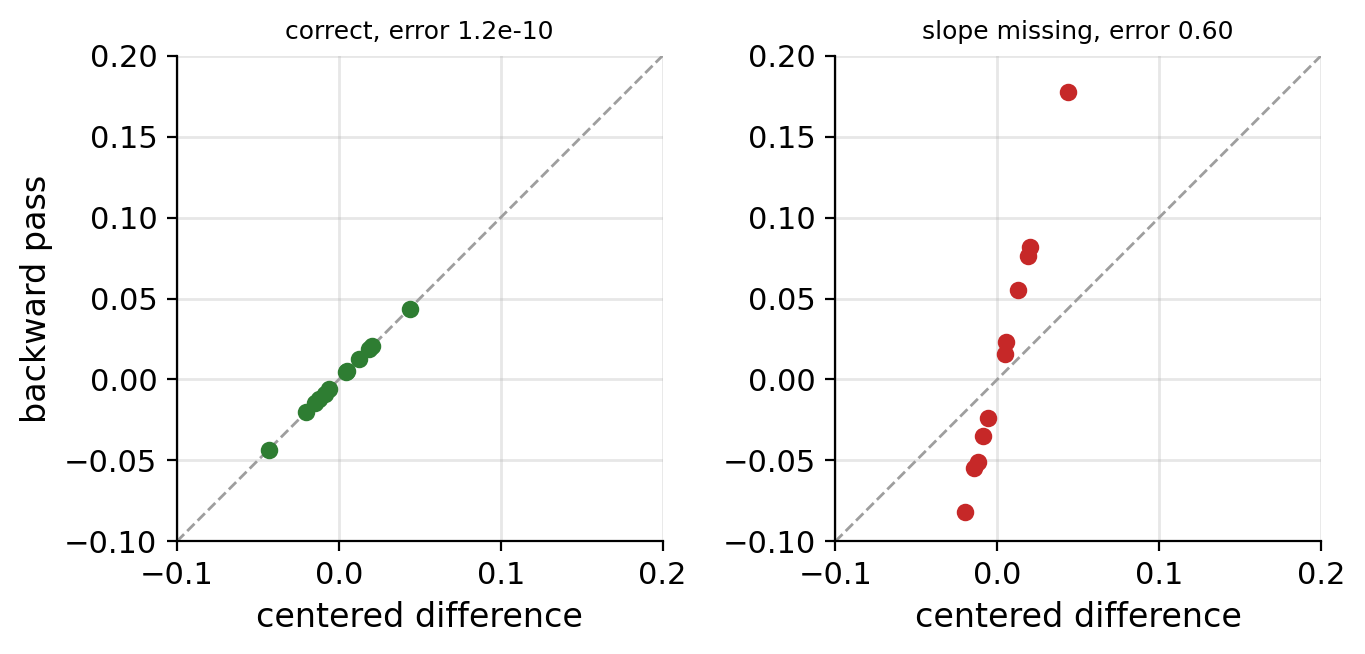
On the 3-4-2 batch, first row of \(\partial \mathcal{L} / \partial \mathbf{W}^{(1)}\)
- Centered difference: \([{-0.014},\ 0.044,\ {-0.020}]\)
- Correct backward pass: the same, relative error about \(10^{-10}\)
- Slope missing: \([{-0.055},\ 0.177,\ {-0.082}]\), relative error \(0.60\)
Detected: any wrong line of the backward pass
- The difference quotient uses the forward pass and the loss only
Not detected: a wrong forward pass, a wrong loss
- Both sides share them
ReLU at the kink
- A parameter with some \(s_i\) within \(\epsilon\) of zero: \(w + \epsilon\) and \(w - \epsilon\) on different sides of the kink
- Difference quotient wrong at that entry
- Check with a sigmoid, or exclude such entries
Forward, Backward, Update on Real Data: Three Species From Two Measurements
Example: Palmer penguins
- 342 birds, bill length and flipper length
- Three species as the classes
- 240 training, 102 test, features standardized
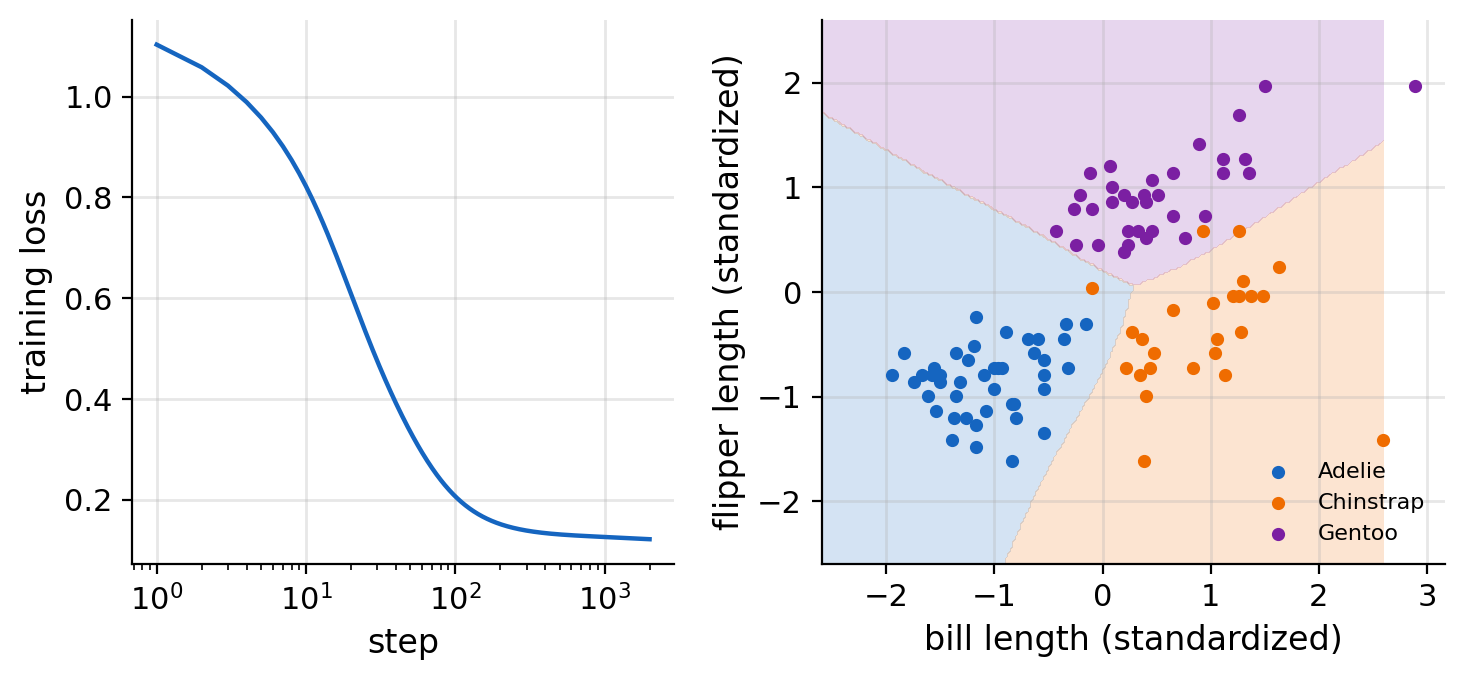
Network: \(2\)-\(8\)-\(3\), sigmoid hidden layer, softmax output
- Fit by the forward, backward, and update lines from random weights of spread \(0.5\)
- Full training batch, \(\eta = 0.5\), \(2{,}000\) steps
Training loss: \(1.103\) to \(0.122\)
| Model | Training birds correct | Test birds correct |
|---|---|---|
| Two-layer network | \(229\) of \(240\) | \(99\) of \(102\) |
| Multinomial logistic regression | \(229\) of \(240\) | \(99\) of \(102\) |
Same count as multinomial logistic regression on the same split
- The hidden layer bends the regions and changes no decision
- The species separate along nearly straight lines in these two features
Data: Palmer Penguins, A. M. Horst, A. P. Hill, K. B. Gorman, 2020 (CC0); collected by K. Gorman and Palmer Station LTER
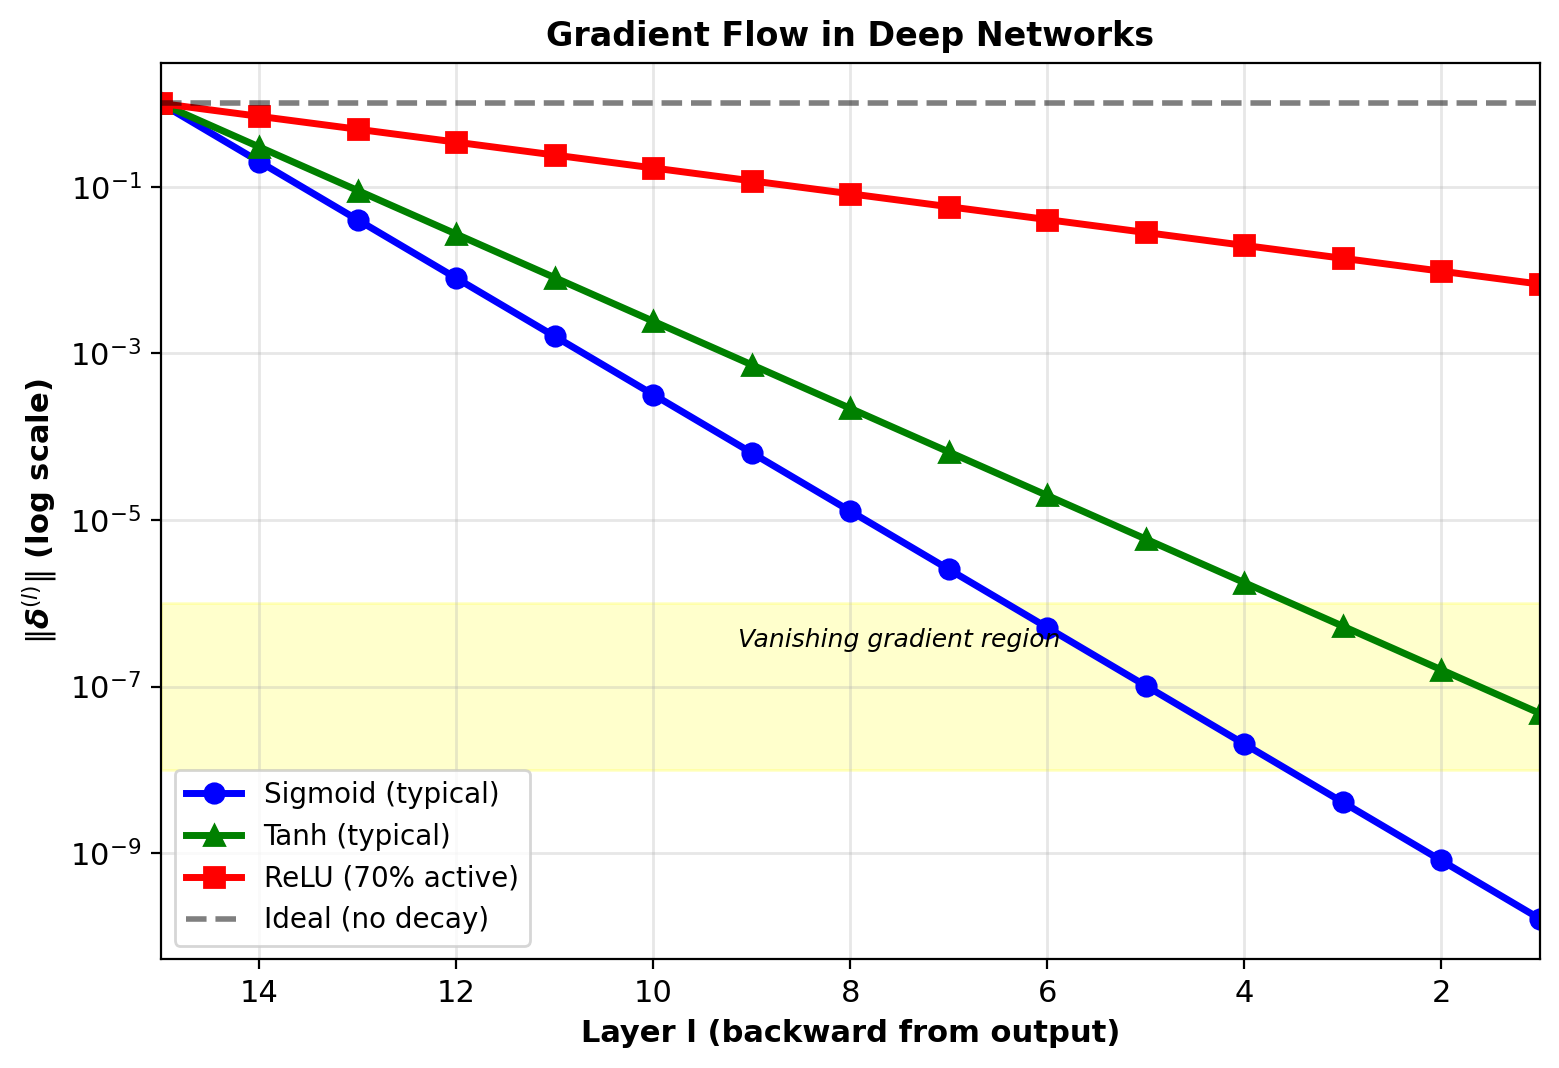
Sigmoid Layers Shrink the Gradient
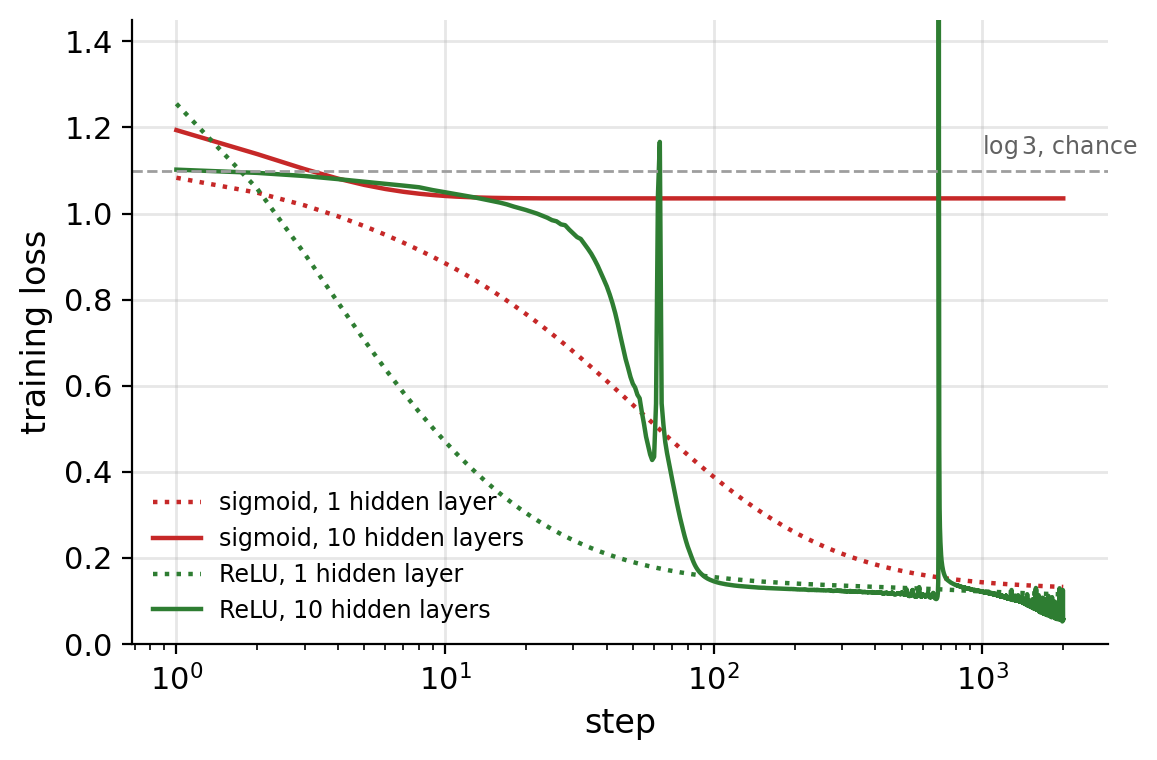
Network: \(2\)-\(16\)-\(\cdots\)-\(16\)-\(3\), ten hidden layers of \(16\) units, the \(240\) training penguins
- Weights \(\mathcal{N}(0, 1/n_{\text{in}})\) so that each \(s_i\) starts with variance near one, biases zero, at initialization
Measured: \(\|\partial \mathcal{L} / \partial \mathbf{W}^{(l)}\|_F\) by layer, one backward pass
- Sigmoid: \(7.0 \times 10^{-1}\) at the output layer, \(8.1 \times 10^{-7}\) at the first
- Ratio first to last: \(1.2 \times 10^{-6}\), a factor \(0.26\) per layer
- Tanh: ratio \(3.0\)
- ReLU: ratio \(0.49\)
Mean slope per hidden layer, sigmoid: \(0.21\) to \(0.24\)
- Product over the ten layers: \(4.5 \times 10^{-7}\)
- The weight matrices, largest singular values \(1.3\) to \(2.0\), multiply in the same product
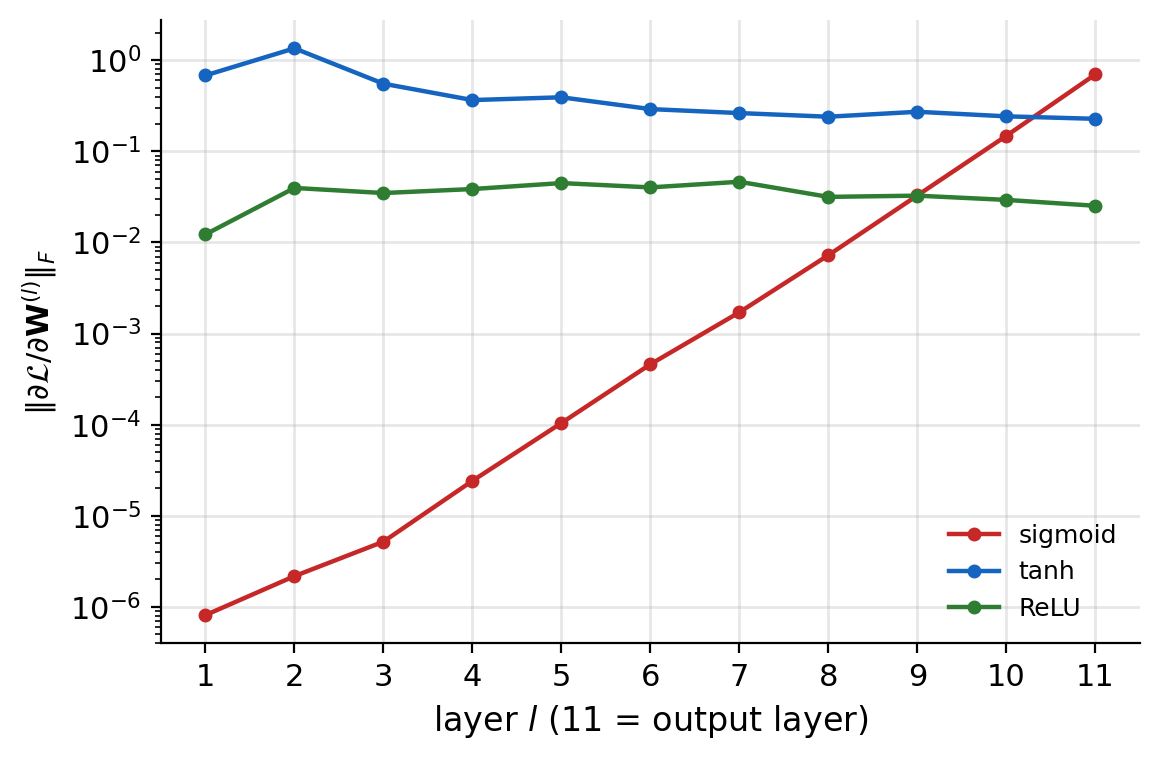
Tanh and ReLU slopes are \(1\) where the unit is active: the gradient retains its size through every layer
ReLU Layers Preserve the Gradient
Trained: by the forward, backward, and update lines, \(\eta = 0.1\), \(2{,}000\) full-batch steps, hidden layers of \(16\) units
| Activation | Layers | Loss | Test, of \(102\) | \(\|\mathbf{W}^{(1)} - \mathbf{W}^{(1)}_0\|_F\) |
|---|---|---|---|---|
| Sigmoid | \(1\) | \(0.132\) | \(99\) | \(3.09\) |
| Sigmoid | \(5\) | \(1.034\) | \(43\) | \(0.10\) |
| Sigmoid | \(10\) | \(1.035\) | \(43\) | \(0.000\) |
| ReLU | \(1\) | \(0.115\) | \(100\) | \(1.44\) |
| ReLU | \(5\) | \(0.086\) | \(96\) | \(0.78\) |
| ReLU | \(10\) | \(0.056\) | \(100\) | \(0.72\) |
- Sigmoid at five and ten layers: the loss stays near \(\log 3 = 1.099\), chance for three classes, and the first layer does not move
- ReLU at every depth: the first layer moves and the loss falls
Open problem: gradients of one size at every depth
- Activation: the slope, \(1/4\) at most for the sigmoid, \(1\) for ReLU
- Weight scale: the \(\|\mathbf{W}^{(l)}\|\) in the same product
- Step size: the five-layer ReLU network at \(\eta = 0.5\) diverges within the \(2{,}000\) steps
Backward pass exact at every depth: what shrinks is the gradient itself, and the remedies change the network, not the algorithm
EE 541 Convention: Numerator Jacobian, Column Gradient
Jacobian of \(\mathbf{y} = g(\mathbf{x})\): numerator convention, \(m \times n\) \[\mathbf{J} = \frac{\partial \mathbf{y}}{\partial \mathbf{x}}, \qquad J_{ji} = \frac{\partial y_j}{\partial x_i}\]
Gradient of a scalar: denominator convention, a column the shape of \(\mathbf{x}\) \[\nabla_{\mathbf{x}} f \in \mathbb{R}^{n}, \qquad \mathbf{x} \leftarrow \mathbf{x} - \eta\, \nabla_{\mathbf{x}} f\]
Chain rule: pre-multiply by the Jacobian transpose \[\nabla_{\mathbf{x}} f = \mathbf{J}^T\, \nabla_{\mathbf{y}} f, \qquad [n \times m][m \times 1] = [n \times 1]\]
Example: \(\mathbf{y} = \mathbf{W}\mathbf{x}\), \(\mathbf{W}\) of shape \(2 \times 3\), \(f = \|\mathbf{y}\|^2\) \[\mathbf{W} = \begin{bmatrix} 0.5 & 0.3 & -0.1 \\ -0.2 & 0.4 & 0.2 \end{bmatrix}, \qquad \mathbf{x} = \begin{bmatrix} 1 \\ 2 \\ -1 \end{bmatrix}\] \[\mathbf{y} = \begin{bmatrix} 1.2 \\ 0.4 \end{bmatrix}, \qquad \nabla_{\mathbf{y}} f = 2\mathbf{y} = \begin{bmatrix} 2.4 \\ 0.8 \end{bmatrix}\]
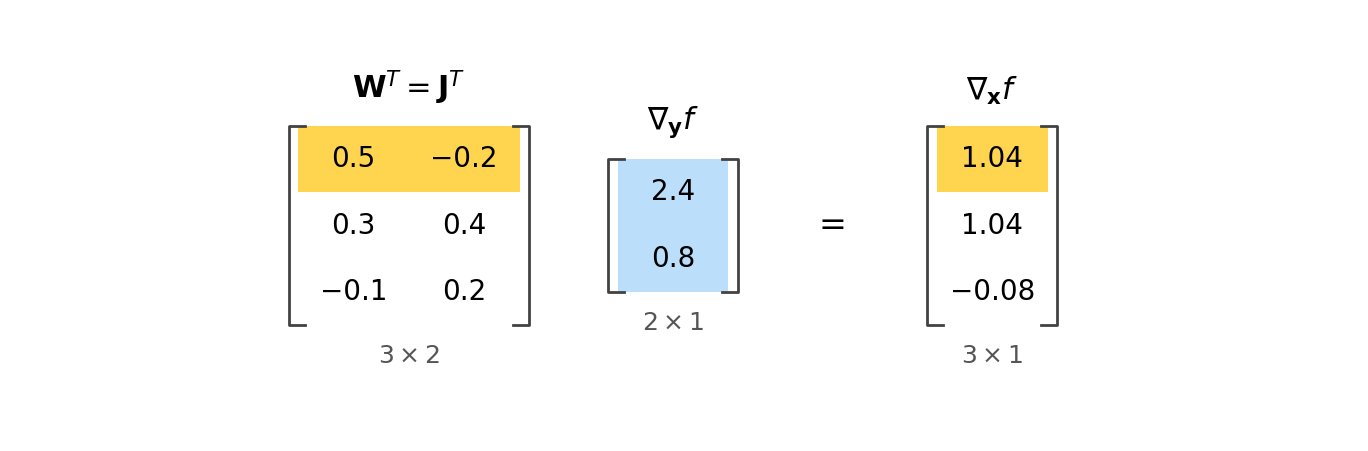
Entry 1: \(\;0.5 (2.4) + (-0.2)(0.8) = 1.04\), the first column of \(\mathbf{W}\) against \(\nabla_{\mathbf{y}} f\)
Mixed convention: numerator Jacobian, denominator gradient, the common choice in machine learning texts
Numerator Convention: Row Gradient, Chain Rule in Forward Order
Numerator convention throughout: the gradient of a scalar is its \(1 \times n\) Jacobian, a row \[\frac{\partial f}{\partial \mathbf{x}} = (\nabla_{\mathbf{x}} f)^T \in \mathbb{R}^{1 \times n}\]
Chain rule: post-multiply, the factors in the order of the forward pass \[\frac{\partial f}{\partial \mathbf{x}} = \frac{\partial f}{\partial \mathbf{y}}\, \frac{\partial \mathbf{y}}{\partial \mathbf{x}}, \qquad [1 \times n] = [1 \times m][m \times n]\]
- Vector-valued steps compose the same way: \(\partial f / \partial \mathbf{x} = \partial f / \partial \mathbf{z} \cdot \partial \mathbf{z} / \partial \mathbf{y} \cdot \partial \mathbf{y} / \partial \mathbf{x}\), every factor a Jacobian
Update: the transpose is in the update instead \[\mathbf{x} \leftarrow \mathbf{x} - \eta\, \Big(\frac{\partial f}{\partial \mathbf{x}}\Big)^T\]
Same example: \(\partial f / \partial \mathbf{y} = [2.4,\ 0.8]\), a row
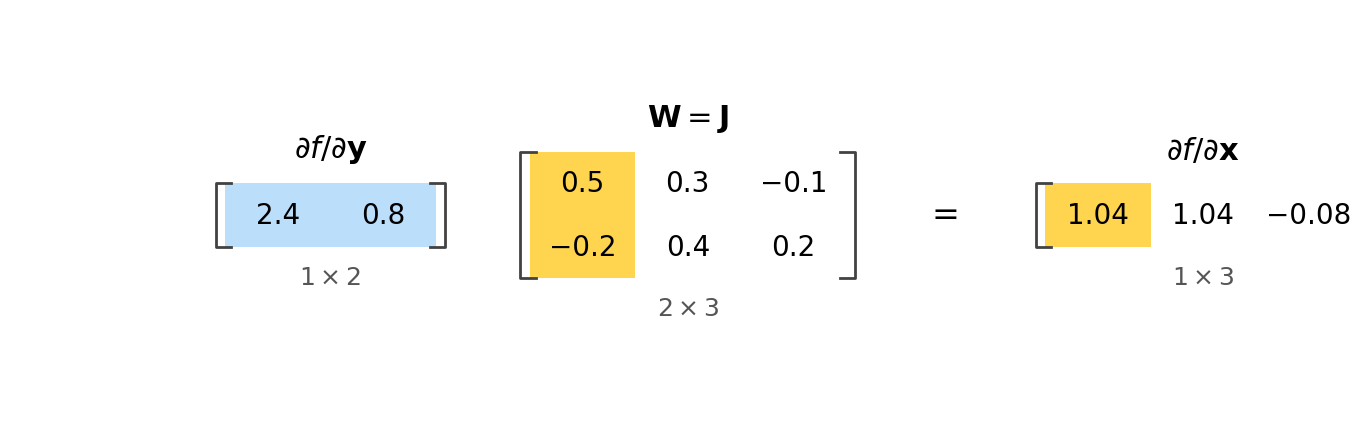
Entry 1: \(\;2.4 (0.5) + 0.8 (-0.2) = 1.04\), \(\partial f / \partial \mathbf{y}\) against the first column of \(\mathbf{W}\)
One object for every derivative: a scalar’s gradient and a vector function’s Jacobian are both Jacobians, and the chain rule is one rule